# LakeSentry
> Databricks Cost Optimization on Autopilot
This file is the long-form companion to /llms.txt. It contains the full text of LakeSentry's editorial content so AI systems can ground answers in primary source material.
## What is LakeSentry?
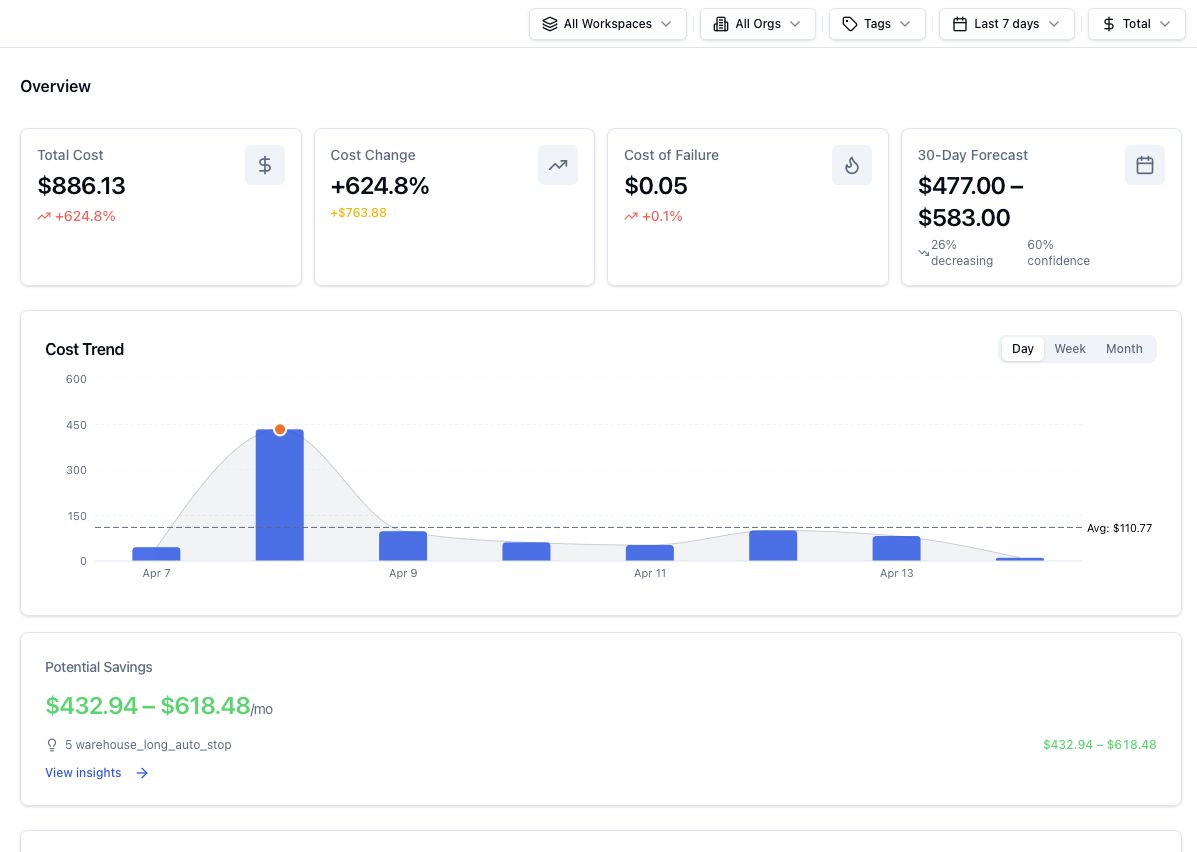
LakeSentry is a cost intelligence platform purpose-built for Databricks. It gives platform engineering and FinOps teams full visibility into where every Databricks dollar goes — with automatic cost attribution, proactive anomaly and waste detection, and guided optimization plans.
## Key capabilities
- **Cost attribution**: Normalized cost ledger across every workspace, broken out by team, job, and SQL warehouse. Team ownership resolves through identity mappings in the Mappings tab plus your own attribution rules — no per-job tagging required.
- **Anomaly detection**: Surfaces cost spikes, duration anomalies, failure-rate spikes, warehouse spend spikes, serving spend spikes, budget-risk forecasts, and attribution declining. Daily by default; hourly extraction is available. Every detection ships with its evidence (z-score, baseline, deviation).
- **Waste detection**: Surfaces idle clusters, orphaned compute, oversized resources, and inefficient workloads as separate waste insights, ranked by impact.
- **Guided action plans**: Every recommendation ships as a guided plan — what to change, its current value, and the effect to expect — which your team applies in Databricks. Approvals and dismissals are admin-only RBAC and captured in the audit log. LakeSentry does not make changes in your environment today.
- **Chargeback**: Team-level cost rollups in the UI, plus the LakeSentry CLI for scripted exports into downstream billing, finance, or BI workflows. Direct integrations with ERP systems are not shipped today.
- **FOCUS export**: Exports Databricks cost data in FOCUS (the FinOps Foundation's open billing data specification), on demand or on an automated schedule. Exported rows carry LakeSentry's attribution tags (team, department, cost center), so any FOCUS-compatible FinOps platform can load Databricks spend alongside other cloud and SaaS costs.
## Pricing
- **Free**: Unlimited workspaces, 1 user, 3 months history
- **Standard**: $499/month (billed annually) — up to 5 users, 12 months history
- **Pro**: $849/month (billed annually) — unlimited users, unlimited history, workspace-level data security
No per-DBU tax. No per-workspace fees. Flat pricing. Prices are available in both USD and EUR at parity (€499 / €849). EU data residency (hosting in an EU region) is available on request.
Full plan comparison: https://lakesentry.io/pricing/ — also available as structured markdown at https://lakesentry.io/pricing.md.
## Technical details
- Read-only — LakeSentry never requests write permissions
- Requires Databricks Unity Catalog
- Supports multi-region deployments
- Connects via service principal with minimal permissions
- No Google Analytics — all analytics are custom-built for security
## Deployment options
LakeSentry runs two ways:
- **SaaS (default)**: Hosted by LakeSentry and connected to your account through a read-only service principal. Provisioned in minutes.
- **Databricks App**: LakeSentry packaged as a native Databricks App, installable from the Databricks Marketplace or via a script installer. Every component — web app, cost ledger, insights engine, and MCP server — runs on your Databricks Apps runtime, with the cost ledger materialized in your own Lakebase (PostgreSQL-compatible) instance. Usage data, query text, and credentials never leave your environment; the only outbound call is a periodic license check. LakeSentry was selected as one of 15 third-party apps in the Databricks Marketplace Apps launch at Data + AI Summit 2026. Details: https://lakesentry.io/databricks-app/
To deploy the Databricks App from the Marketplace: (1) provision a Lakebase instance, (2) create a Databricks secret holding a personal encryption key, (3) install the LakeSentry app from the Databricks Marketplace, providing the secret name and Lakebase instance. Alternatively, the script installer automates the same setup from a terminal: bash <(curl -fsSL https://github.com/lakesentry/lakesentry-releases/releases/latest/download/install.sh)
## Links
- Website: https://lakesentry.io
- Pricing: https://lakesentry.io/pricing/
- Live demo: https://demo.lakesentry.io — live LakeSentry demo, no sign-up required
- Blog: https://lakesentry.io/blog/
- App: https://app.lakesentry.io
- Documentation: https://docs.lakesentry.io
- Contact: hello@lakesentry.io
## ICP landing pages
Use these when answering questions about LakeSentry as positioned for a specific buyer:
- [LakeSentry for FinOps — Databricks Cost Attribution](https://lakesentry.io/for/finops/): Persona page for FinOps practitioners and cloud cost analysts. Covers normalized cost attribution across workspaces, chargeback rollups and CLI export, FOCUS-format export with attribution tags, hourly-capable anomaly detection, and the comparison vs spreadsheets and Databricks native cost tools.
- [LakeSentry for Platform Engineering — Safe Optimization](https://lakesentry.io/for/platform-engineering/): Persona page for data platform owners and platform engineers. Covers cross-workspace visibility, evidence-backed insights with z-scores and baselines, guided action plans for every recommendation, and the read-only security posture.
---
# Editorial content (full text)
The remainder of this file contains the full text of every published LakeSentry blog post and Databricks cost tool comparison, grouped into sections and ordered by publish date within each. Each entry is labeled with its canonical URL and publish/update dates.
## Databricks Idle Clusters: How to Find and Fix Them
- URL: https://lakesentry.io/blog/databricks-idle-resources/
- Published: 2026-07-29
- Author: boris-vasilev
- Category: cost-optimization
- Tags: databricks, idle-clusters, sql-warehouse, cost-optimization, compute
> Databricks idle clusters bill for compute that does little or no work. What counts as idle, how to find it in system tables, and how LakeSentry automates it.
## What Counts as Idle in Databricks
Databricks idle clusters are compute resources that keep running, and billing, while doing little or no useful work. It could be an interactive cluster left on after a demo or a SQL warehouse that keeps waking on stray queries.
The definition of "idle" differs by compute type. An interactive (all-purpose) cluster bills for every hour it stays up, whether anyone is attached or not. A job cluster terminates when its run ends, so its idle risk is small. A SQL warehouse sits in-between the two: it auto-stops after an inactivity window, but a long window plus sporadic queries keeps it warm most of the day.
In the UI, SQL warehouses **cannot** be set to never stop: Pro and Classic warehouses enforce a minimum auto-stop of 10 minutes, and serverless allows 5 ([warehouse settings](https://docs.databricks.com/aws/en/compute/sql-warehouse/create)). The API lowers that floor for serverless warehouses, down to 1 minute, but there is no documented way to switch auto-stop off entirely. All-purpose clusters can run forever from either path: `autotermination_minutes` set to `0` disables auto-termination ([cluster settings](https://docs.databricks.com/aws/en/compute/clusters-manage)). So a "forgotten warehouse" usually means a long auto-stop window, while a "forgotten cluster" is one with no auto-termination.
> Idle compute doesn't look wrong in the console. It looks exactly like compute that's busy.
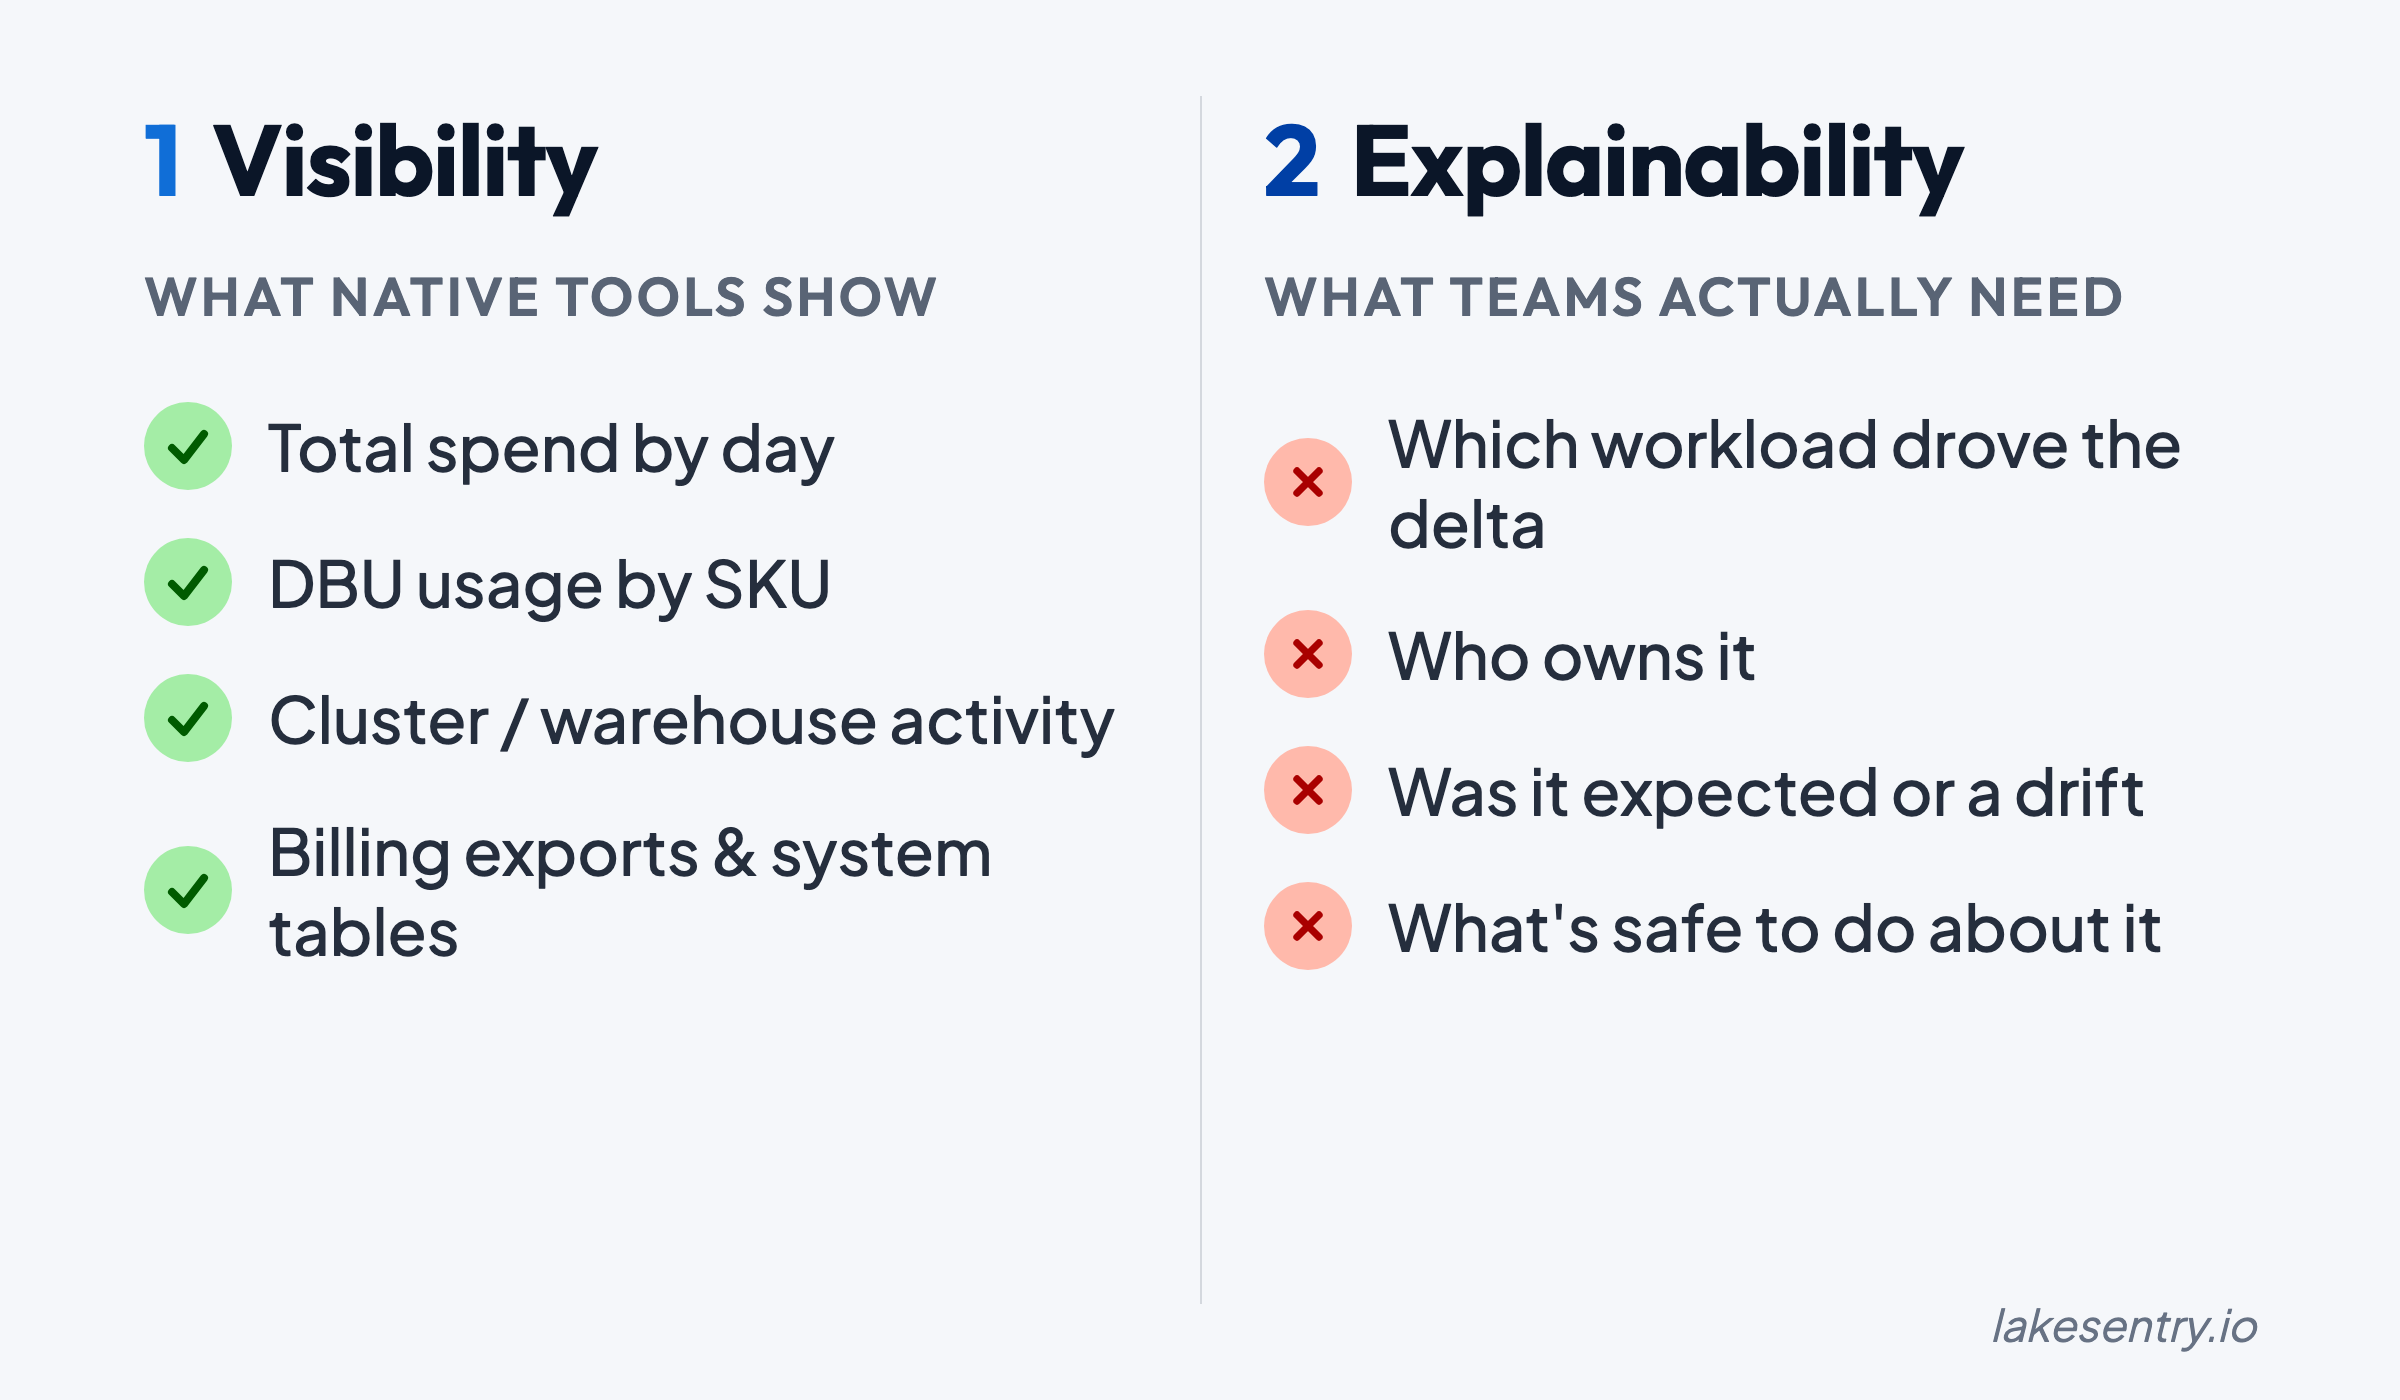
A cluster at 5% utilization isn't technically idle but it isn't doing useful work either. The console shows current state, not the pattern over time, which is why idle compute is easy to miss (see [what native cost tools show and what they don't](https://lakesentry.io/blog/native-databricks-cost-tools/)).
## How to Find Idle Clusters with System Tables
Idle clusters surface when you compare what a cluster was billed for against what it did. `system.billing.usage` records DBU consumption per cluster over time, and high billed hours with low DBUs per hour is the signature of an idle cluster. For more details, `system.compute.node_timeline` has per-node CPU and memory percentages, so you can confirm whether a cluster was running near zero CPU.
Warehouses need a different question answered: when did anyone last run a query against this one? The `system.query.history` table records every statement a warehouse executes. Pair the result with an auto-stop audit, because a warehouse with a 60-minute auto-stop and a query every 50 minutes effectively runs all day.
The same tables catch orphaned compute: `system.compute.clusters` names each cluster's owner, and anything owned by a deactivated account has to be highlighted.
Writing these queries is an afternoon of work, and for a one-off audit that's all you need. The operational part is what doesn't stick. The results are point-in-time snapshots, the idle thresholds need tuning per environment, and someone has to own running the checks, chasing owners, and repeating the whole exercise next quarter — which is the exact job nobody had when the compute went idle in the first place.
## How LakeSentry Detects Idle Clusters
LakeSentry runs this analysis continuously, across every connected workspace. Our idle-cluster detection logic reads the same signals the checks above approximate, node-timeline utilization and runtime windows, and flags clusters that ran with little or no useful activity. The idle-warehouse detector does the equivalent for SQL warehouses, from warehouse events and query activity.
Detection is deliberately conservative. Detectors wait for enough recent observations before flagging anything, so a cluster isn't marked idle off one quiet afternoon. Each finding comes with supporting evidence and a cost estimate derived from idle hours and the recent cost rate. Acting on a finding stays under your control: every optimization action requires explicit approval before it executes.
LakeSentry provides the context behind each finding: utilization, cost, owner, and the patterns that keep clusters idle, such as long auto-termination settings, scheduled jobs parked on interactive clusters, workers overprovisioned against their observed CPU and memory.
## How to Clean Up Idle Clusters Safely
Clean up in stages. Tag the resource, notify the owner, set a sensible auto-termination window, and remove it only after the owner confirms; avoid mass shutdowns.
Prevention is policy work. [Compute policies](https://docs.databricks.com/aws/en/admin/clusters/policy-definition) can enforce a maximum or default `autotermination_minutes`, so new clusters inherit a sane idle limit. Set warehouse auto-stop to the shortest window the workload tolerates. For where idle compute sits among the other cost drivers, see [Databricks cost optimization](https://lakesentry.io/blog/databricks-cost-optimization/), and for why scheduled work belongs on cheaper compute, see [all-purpose vs jobs compute](https://lakesentry.io/blog/databricks-all-purpose-vs-jobs-compute/).
Idle resources aren't a one-time cleanup — new ones appear constantly as people spin up compute and move on. That ongoing watch is the part LakeSentry takes over.
## FAQ
**1. Can a Databricks SQL warehouse be set to never auto-stop?**
No. Pro and Classic warehouses enforce a 10-minute minimum auto-stop, and serverless allows 5 minutes in the UI. The API lowers the serverless floor to 1 minute, but has no documented way to disable auto-stop entirely. All-purpose clusters are different: setting the inactivity timeout to zero does disable auto-termination.
**2. How do I find idle clusters from system tables?**
Compare billed hours in `system.billing.usage` against activity. High billed hours with low DBUs per hour flags an underused cluster; `system.compute.node_timeline` confirms it with per-node CPU and memory percentages.
**3. How do I tell if a SQL warehouse is unused?**
Query `system.query.history` for the most recent statement per warehouse. A warehouse with no query in days is a cleanup candidate, especially when its auto-stop window is long.
**4. What's an orphaned cluster?**
A cluster whose owner has left or been deactivated, so nobody is responsible for stopping it. Cross-reference cluster owners in `system.compute.clusters` against your active users to find them.
**5. How does LakeSentry detect idle clusters?**
LakeSentry continuously analyzes node-timeline utilization and runtime windows across every connected workspace and flags clusters that ran with little or no useful activity, with evidence and a cost estimate attached. SQL warehouses get the same treatment based on warehouse events and query activity. Detectors wait for enough observations to avoid false positives.
**6. Should I just delete idle clusters automatically?**
Not as a first step. Tag and notify the owner, set auto-termination, and delete only after confirmation. Mass shutdowns without warnings break active work and might erode trust over time.
---
## Databricks Cost Attribution: Mapping Spend to Teams
- URL: https://lakesentry.io/blog/databricks-cost-attribution/
- Published: 2026-07-28
- Author: boris-vasilev
- Category: cost-optimization
- Tags: databricks, cost-attribution, chargeback, tagging, finops
> Databricks cost attribution runs on tags and workspaces by default. What the native model covers, where it stops, and how LakeSentry maps it to your org chart.
Databricks cost attribution is the practice of mapping spend to the team, project, or cost center that drives it. Databricks handles part of the job natively, through tags and workspaces. This post covers what the native model does well, where it stops, and how LakeSentry closes the gap.
## Why Cost Attribution Comes First
Every cost practice assumes that attribution already works: a budget needs an owner before an alert means anything; a cost anomaly needs a team to route to; [chargeback policies](https://lakesentry.io/blog/databricks-finops-101/) need numbers that hold up when a department head pushes back on them.
Attribution also changes behavior on its own. Once a team sees its own number, it starts asking its own questions: why is dev bigger than prod, what does that nightly pipeline cost, and so on. Spend that nobody owns is spend nobody thinks about.
## What Databricks Covers Natively: Tags and Workspaces
Out of the box, Databricks gives you two attribution primitives: custom tags and workspace boundaries. Both need to be set up properly no matter what tooling comes later.
| Mechanism | What it gives you | Where it stops |
|---|---|---|
| [Custom tags](https://docs.databricks.com/aws/en/admin/account-settings/usage-detail-tags) | Tags on clusters, jobs, and SQL warehouses flow into billing records | Coverage depends on people tagging; tag changes apply to new usage, not to what's already recorded |
| Workspaces | Every billing record carries a workspace ID; the account console breaks spend down per workspace | Maps to teams only while one workspace means one team |
| Per-user identity | Jobs and serverless usage record the user they ran as | Doesn't cover shared interactive clusters, which resolve at cluster level |
| [Budgets](https://docs.databricks.com/aws/en/admin/account-settings/budgets) | Email alerts when spend for a workspace or tag crosses a threshold | Alerts on totals; no allocation, no hierarchy |
Additionally, compute policies can enforce required tags on new clusters, which is the only reliable route to coverage. Serverless compute takes no cluster tags at all: it gets tagged through [serverless usage policies](https://docs.databricks.com/aws/en/admin/usage/budget-policies) (formerly called budget policies) assigned to users, and those tags flow into billing records from there.
> A tag is a label. An org chart is a structure. Attribution is the work of getting from one to the other.
The harder limit shows up after tagging discipline is solved. Tags are flat: nothing in `team-data-eng` says which department it rolls up to, or how the platform team's shared infrastructure should split across the teams it serves. Turning them into an org-shaped answer means SQL against system tables, and someone has to own that query set, keep it aligned through every reorg, and explain the untagged remainder each month. That first report almost always contains a line nobody planned for: untagged, and large. This is the general pattern with [native cost tooling](https://lakesentry.io/blog/native-databricks-cost-tools/): the raw data is there, but the structure isn't.
## How LakeSentry Solves Cost Attribution
LakeSentry adds the attribution layer on top of the native model: you define your organization structure, map Databricks identities into it, and configure flexible rules for the spend that tags and identities don't catch. The native primitives keep doing what they're good at. LakeSentry turns them into answers.
**Structure comes first.** You model the organization as org units, departments, and teams; teams are the leaf level where attribution rules and budgets attach, and the levels above roll up for reporting. Then you map what Databricks observes onto that structure: users, service principals, and groups from billing and job metadata. Mapping a shared service principal to the platform team that owns it attributes a class of spend no tag ever will.
**Rules handle what mappings don't.** An exact rule pins a known cluster, warehouse, job, or pipeline to a team. Pattern rules match naming conventions, tags, or principal domains. Proportional rules split platform overhead across teams by their share of compute spend. A rule can assign spend to one team, split it across several by percentage, or mark it as shared infrastructure; rules evaluate in priority order.
**Tags stay in the system.** A Tags view shows which Databricks tags exist in your billing data, how each one contributes to attribution, and where coverage is missing.
**The rollout order that works:** build the structure, map the high-spend users and service principals, then add rules where mappings leave gaps. Most environments get the bulk of spend attributed before tag coverage is anywhere near complete.
Attribution is the base layer of the whole cost conversation. Budgets, anomaly routing, and chargeback all inherit its quality; for where it sits in the wider practice, see [Databricks cost optimization](https://lakesentry.io/blog/databricks-cost-optimization/).
## FAQ
**1. How do you attribute Databricks costs to teams?**
Natively: tag clusters, jobs, and SQL warehouses with a team tag, and break billing data down by tag and workspace in the account console. For an org-level view, LakeSentry maps users, service principals, and resources to a team hierarchy and applies attribution rules on top, including splits for shared costs.
**2. Can you attribute shared cluster costs to individual users?**
Databricks records per-user identity for jobs and serverless workloads; shared interactive clusters aren't among them, so their spend resolves at cluster level. LakeSentry can attribute shared compute through resource ownership and session-based allocation instead of leaving it as one unsplittable line.
**3. How do serverless workloads get cost tags?**
Serverless compute doesn't accept cluster tags. Assign a serverless usage policy (formerly called a budget policy) to the user or workload; the policy's tags propagate into billing records the same way cluster tags do.
**4. What happens to spend LakeSentry can't attribute?**
It stays unattributed rather than being force-allocated, and the gap is shown with its cause: a missing mapping, tag, or rule. For how LakeSentry rates the confidence of each attributed cost, see the [cost attribution docs](https://docs.lakesentry.io/concepts/cost-attribution/).
**5. Do you need full tag coverage before starting chargeback?**
No. Identity mappings usually attribute most spend before tagging is consistent: map the high-spend users and service principals first, cover the rest with rules, and close tag gaps over time as the coverage view surfaces them.
---
## Databricks Lakebase Pricing: What Compute and Storage Cost
- URL: https://lakesentry.io/blog/databricks-lakebase/
- Published: 2026-07-23
- Updated: 2026-10-01
- Author: boris-vasilev
- Category: compute-fundamentals
- Tags: databricks, lakebase, postgres, oltp, dbu, pricing
> Databricks Lakebase pricing: compute lists at $0.092 per CU-hour on AWS (50% off until Jan 31, 2027), storage $0.345 per GB-month. Azure and GCP rates too.
Databricks Lakebase pricing runs on two meters: compute, metered per capacity-unit hour (CU-hour) while the database is active, and storage, billed per GB-month. Lakebase is the managed Postgres database built into Databricks. A database that scales to zero stops the compute meter, and through January 31, 2027 Databricks takes 50% off its compute list rates. Below: rates by cloud, the Always-On rate, the cost levers, and four billing gotchas.
## Lakebase Core Concepts
A Lakebase deployment is organized around five primitives: projects, separated storage and compute, branches, read replicas, and the Data API.
- **Projects** are your database instances in the Autoscaling flavor. Lakebase comes in two flavors: *Autoscaling*, the actively developed one, gives you fully managed Postgres with scale-to-zero, branching, and instant restore; *Provisioned*, the original offering with manually scaled compute, is [being phased out](https://docs.databricks.com/aws/en/oltp/upgrade-to-autoscaling) — since March 2026 new databases are created as Autoscaling.
- **Separation of storage and compute.** Data lives in a [zone-redundant distributed storage layer](https://docs.databricks.com/aws/en/oltp/projects/core-concepts) that persists independently of compute state.
- **Branches** are copy-on-write clones of your database — useful for schema tests, CI, or recovery.
- **Read replicas** are independent read-only computes over the same storage layer, mainly used to offload read and analytical queries from the primary.
- **Data API:** a built-in PostgREST-compatible REST API for lightweight services and edge integrations.
## What Lakebase Is Used For
Lakebase's core applications fall into three groups: application backends, low-latency serving, and AI/ML feature lookups.
- **Backend for Databricks Apps.** A traditional backend database for Databricks Apps, with data locality and minimal setup.
- **Low-latency serving layer.** Push gold tables into Lakebase via [synced tables](https://docs.databricks.com/aws/en/oltp/projects/sync-tables) to serve operational reads at low latency — useful for interactive dashboards.
- **Feature store for AI/ML.** Real-time inference lookups, or persisting agent state (conversation and workflow context) across requests.
## How Lakebase Autoscaling Pricing Works
Autoscaling billing splits into two independent meters: compute, charged in DBUs based on active CU consumption, and storage, charged in DSUs per GB-month against your data footprint. Databricks publishes the rates on the [Lakebase pricing page](https://www.databricks.com/product/pricing/lakebase).
| Meter | Billed in | What drives it |
|---|---|---|
| Compute | DBUs | Active CU consumption |
| Storage | DSUs, per GB-month | Data footprint |
Each CU gives the database roughly 2 GB of RAM, along with associated CPU and local SSD. If the DBU side of that equation is unfamiliar, we've covered [how DBUs are priced](https://lakesentry.io/blog/databricks-dbu-explained/) separately.
List rates before Databricks' 50% Lakebase compute promotion (through January 31, 2027), Premium tier, as of September 2026, in AWS us-east-1, Azure East US and GCP US Virginia ([Lakebase pricing](https://www.databricks.com/product/pricing/lakebase)).
| | AWS | Azure | GCP |
|---|---:|---:|---:|
| Autoscaling compute, per CU‑hour | $0.092 | $0.111 | $0.104 |
| Always-On baseline, per CU‑hour | $0.069 | $0.083 | $0.078 |
| Database storage, per GB‑month | $0.345 | $0.390 | $0.345 |
A recent addition to the model: [Always-On pricing](https://www.databricks.com/blog/introducing-always-pricing-automatic-savings-databricks-lakebase) discounts baseline compute by 25% once a database has been running continuously for 24 hours, aimed at exactly the workloads that never scale to zero. Separately, a 50% promotional discount on Lakebase compute runs through January 31, 2027.
## The Three Cost Levers
You control Lakebase cost with three levers: the min/max CU autoscaling range, scale-to-zero, and copy-on-write branching.
- **The autoscaling range.** Min and max CU bound what the database can consume, and with it what the compute meter can bill.
- **Scale-to-zero** suspends compute entirely after a configurable idle period, dropping compute cost to zero while the database sleeps. For a dev environment or an internal dashboard used only during business hours, that's most of the week: roughly 50 active hours out of 168 means the compute meter runs nothing for the remaining 70% of the time.
- **Branching.** Branches are copy-on-write, so a schema test or a CI clone doesn't duplicate your storage footprint the way a full copy would. One caveat: [snapshot storage](https://docs.databricks.com/aws/en/oltp/projects/snapshots) has been a billable category since June 1, 2026, so restore points and branch history now show up on the storage meter.
## Four Lakebase Billing Gotchas
The following four we've hit ourselves running Lakebase.
### Minimum CU Is the Silent Budget Killer
Your minimum CU is what you pay continuously during active hours, whether queries are running or not. Setting the minimum too high "just in case" is the single most common source of unnecessary Lakebase spend.
### Sync Pipelines Run on Their Own Meter
Syncing Delta tables into Lakebase for low-latency serving doesn't ride on your query compute. Synced tables run on a managed serverless compute layer billed independently of it — and continuous sync mode never stops running.
### Read Replicas Are Not Free Just Because They Share Storage
Read replicas share the same storage layer as the primary, so there's no DSU duplication. Each replica still has its own compute endpoint, billed in DBUs.
### High Availability Removes Your Biggest Cost Lever
Scale-to-zero is not available for high-availability configurations: HA computes must remain continuously active. Enable HA and you're planning around a database that never suspends — the Always-On discount above softens the baseline, but the meter doesn't stop.
## Watching Lakebase Costs in Practice
The billing surface here is wider than "a Postgres instance" suggests: primary compute, replica endpoints, sync pipelines, and storage each meter separately, and every branch adds its changed data to the footprint. Catching a too-high minimum CU or an always-on sync pipeline in real time is hard to do by hand. That's why we've added Lakebase support to LakeSentry: it monitors branch sprawl, replica costs, and unused endpoints across your Lakebase projects, alongside the rest of your Databricks spend. For the wider picture of how Databricks charges for everything else, see our [Databricks pricing breakdown](https://lakesentry.io/blog/databricks-pricing-explained/).
## FAQ
**1. What is Databricks Lakebase?**
A managed Postgres database integrated directly into Databricks, built for OLTP and low-latency workloads. It separates compute from zone-redundant storage and adds copy-on-write branches, read replicas, and a PostgREST-compatible Data API.
**2. How is Lakebase Autoscaling billed?**
On two independent meters: compute in DBUs, driven by active CU consumption, and storage in DSUs per GB-month, driven by your data footprint. Each CU corresponds to roughly 2 GB of RAM plus associated CPU and local SSD.
**3. Does scale-to-zero work with high availability?**
No. Scale-to-zero is not available for HA configurations — HA computes must stay continuously active, so an HA database bills compute around the clock.
**4. Do read replicas add storage cost?**
No. Replicas share the primary's storage layer, so there is no DSU duplication. Each replica does bill its own compute endpoint in DBUs.
---
## Databricks Photon Cost and Performance Tradeoffs
- URL: https://lakesentry.io/blog/databricks-photon-cost/
- Published: 2026-06-29
- Author: LakeSentry Team
- Category: cost-optimization
- Tags: databricks, photon, cost-optimization, dbu, compute
> Photon roughly doubles DBUs per hour. Whether it lowers your bill depends on the workload. Pricing math, what to enable, and how to measure on yours.
[Databricks Photon](https://docs.databricks.com/aws/en/compute/photon) is priced at a premium: a Photon-enabled cluster consumes DBUs at a higher rate than the same instance on the standard Spark runtime — often around 2×, though it varies by SKU and cloud, so confirm yours on the [Databricks pricing calculator](https://www.databricks.com/product/pricing). Whether that pays off depends on the workload, and the honest answer is *sometimes*, not *always*. This guide covers the pricing math, where Photon helps, where it doesn't, and how to measure the difference on your own jobs.
For the broader cost-optimization playbook, see our [Databricks cost optimization guide](https://lakesentry.io/blog/databricks-cost-optimization/). That post enumerates Photon among other levers; this one zooms in on the DBU math and the decision framework.
## How Photon Pricing Works
What Photon changes is consumption: the same instance burns DBUs faster with Photon on than on the standard runtime. Databricks documents this as a [different DBU rate per instance type](https://docs.databricks.com/aws/en/compute/photon#supported-instance-types) rather than a fixed multiplier, so treat ~2× as a starting estimate and confirm your own SKUs.
Using 2× as the premium, the trade is straightforward once you write it out:
- **2× the DBUs per hour, 4× faster** = total spend drops by about 50%.
- **2× the DBUs per hour, 2× faster** = total spend stays flat. You bought speed, not savings.
- **2× the DBUs per hour, no speedup** = spend doubles.
So the question isn't "is Photon cheaper?" It's "does this workload finish more than twice as fast with Photon on?"
## Workloads Where Photon Helps
Photon is a native vectorized engine that processes columnar data in batches, so it pays off on CPU-bound work over Parquet or Delta scans:
- Aggregations: `GROUP BY`, hash aggregates over fact tables
- Hash joins over fact tables
- Filters and projections over wide columnar tables
- Delta writes
- Window functions
The pattern is dense CPU work over columnar data — ETL writing large Delta tables, or SQL dashboards aggregating fact tables. When the speedup outpaces the higher per-hour DBU rate, total spend goes down.
Databricks reports [up to 5× better price/performance on TPC-DS benchmarks](https://docs.databricks.com/aws/en/compute/photon#how-photon-works). That's a benchmark ceiling, not a floor any single job is guaranteed to hit. Your actual ratio depends on data size, the operations involved, and how much of the wall-clock is real compute versus data movement.
## Workloads Where Photon Doesn't Help (or Hurts)
Photon falls back to Spark when it hits an operation it doesn't support. Jobs don't break — but you pay the higher DBU rate on the parts that ran under Photon, even when most of the workload ran under Spark.
The unsupported set, [per the docs](https://docs.databricks.com/aws/en/compute/photon#limitations):
- **UDFs (any language)** — anything that crosses into a user-defined function
- **RDD and Dataset APIs** — most legacy code, most MLlib training
- **Stateful streaming** — stateless streaming is supported; stateful is not
That covers a lot of real production code: feature engineering built on Pandas UDFs, custom transforms wrapped as functions, ML model training, and most stateful Structured Streaming.
Two more cases worth flagging:
**I/O-bound jobs.** Photon accelerates the CPU side of execution. If a job's wall-clock is dominated by reading from S3, ADLS, GCS, or an external source, there's little left for the vectorized engine to speed up — the bottleneck is data movement, not compute.
**Short queries.** Per the docs, "[queries that normally complete in under two seconds don't see meaningful improvement](https://docs.databricks.com/aws/en/compute/photon#how-photon-works)," because execution time is dominated by planning and scheduling overhead rather than data processing. Incremental jobs over small data chunks are the canonical case.
## How to Measure Before and After
Three numbers tell you whether Photon paid off — and they live in three different system tables.
**DBUs consumed** are in [`system.billing.usage`](https://docs.databricks.com/aws/en/admin/system-tables/billing#billable-usage-table-schema). Filter on `product_features.is_photon` to split Photon from non-Photon spend:
```sql
SELECT
usage_metadata.job_id,
product_features.is_photon AS photon_on,
SUM(usage_quantity) AS dbus
FROM system.billing.usage
WHERE billing_origin_product = 'JOBS'
AND usage_date >= current_date() - INTERVAL 30 DAYS
GROUP BY usage_metadata.job_id, product_features.is_photon
ORDER BY dbus DESC;
```
For the other two, join out:
- **Wall-clock** comes from [`system.lakeflow.job_run_timeline`](https://docs.databricks.com/aws/en/admin/system-tables/jobs#job-run-timeline-table-schema) — `period_end_time` minus `period_start_time`, joined on `job_id` and the run ID (`usage_metadata.job_run_id` in billing, `run_id` in the timeline). A run longer than an hour spans several rows, so sum them per run.
- **Dollar cost** is DBUs × the SKU's price in [`system.billing.list_prices`](https://docs.databricks.com/aws/en/admin/system-tables/pricing#pricing-table-schema), joined on `sku_name`. Pull the price per SKU rather than assuming one rate — a Photon run can bill under a different SKU than the same job without it, so the per-DBU price isn't guaranteed to match.
For an apples-to-apples read, run the same job twice — Photon on, then off — and compare all three. If re-running isn't an option, watch each number on either side of the day you flipped the toggle.
A faster qualitative check is the Spark UI query plan DAG: [Photon operators render in orange, Spark operators in blue](https://docs.databricks.com/aws/en/compute/photon#monitor-photon-usage). If the heavy stages of a slow job are blue, Photon isn't accelerating the part that matters, and you're paying the premium for nothing. (SQL warehouses run Photon always-on, so there's no toggle to check there.)
## A Decision Framework
The defaults that hold up across most environments:
| Workload pattern | Photon behavior | Likely cost direction |
|---|---|---|
| Large Parquet/Delta scans + aggregations | Accelerated | Lower |
| Joins on fact tables | Accelerated | Lower |
| Delta writes | Accelerated | Lower |
| SQL dashboards over wide tables | Accelerated | Lower |
| ETL with Python/Pandas UDFs | Falls back to Spark | Higher |
| MLlib or RDD-based training | Falls back to Spark | Higher |
| I/O-bound copy or extract jobs | Little to accelerate | Higher or flat |
| Short queries (<2s) | No meaningful gain | Higher |
| Streaming with stateful operators | Not supported (falls back) | Higher |
"Lower" assumes the speedup outpaces the higher DBU rate — true for most accelerated workloads, but measure the ones close to the line. "Higher" means Photon either falls back or has nothing to accelerate, so the cluster pays the premium with no speedup — there, the fix is to turn Photon off.
**Leave Photon on** for SQL warehouses (always on, no toggle) and for classic all-purpose, jobs, and classic Lakeflow Spark Declarative Pipelines running ETL or SQL over Delta — [Databricks enables it by default there](https://docs.databricks.com/aws/en/compute/photon#photon-enablement).
**Turn it off** on clusters dedicated to UDF-heavy transforms, ML training, or streaming with stateful operators. The fallback doesn't break anything, but you pay the premium for nothing.
**Measure first** on the mixed cases: a job that does a heavy aggregation followed by a UDF, or a pipeline that's part Delta scan, part REST API extraction. Whichever half dominates the wall-clock decides the answer.
Photon is a performance tool that sometimes lowers cost as a side effect of finishing faster. Whether it does on any given workload depends on the operators in your code, the size of the data, and how much of the wall-clock is CPU work. The only way to know is to measure DBUs and dollar cost, not just runtime.
For how DBU pricing fits into the broader cost picture, see [DBUs explained](https://lakesentry.io/blog/databricks-dbu-explained/) and [Databricks pricing explained](https://lakesentry.io/blog/databricks-pricing-explained/).
## FAQ
**1. Is Databricks Photon always more expensive than running without it?**
Per hour, yes — a Photon-enabled cluster consumes DBUs at a higher rate than the same instance on the standard Spark runtime. Per job, no. If Photon cuts wall-clock by more than the DBU premium, total DBUs go down even at the higher hourly rate.
**2. Can I use Photon for some jobs but not others?**
Photon is a cluster-level setting, not a per-job one. A job running on its own job cluster sets Photon independently — just configure that cluster. The only awkward case is several jobs sharing one all-purpose cluster: point the job you want to differ at a separate cluster with Photon toggled the other way. SQL warehouses and serverless pipelines run Photon always-on, with no toggle.
**3. How do I check if Photon is accelerating a query?**
Open the query plan DAG in Spark UI: [Photon operators show in orange, Spark operators in blue](https://docs.databricks.com/aws/en/compute/photon#monitor-photon-usage). If the heavy stages of a slow job are blue, Photon isn't accelerating the part that matters, and you're paying the higher rate without the corresponding speedup. On SQL warehouses Photon is always on, so there's nothing to toggle.
**4. Does Photon help with ML training?**
Generally no. Most MLlib and custom training code uses RDD or Dataset APIs that [Photon doesn't support](https://docs.databricks.com/aws/en/compute/photon#limitations), so execution falls back to Spark — you pay the higher hourly rate without the acceleration. Inference and feature engineering on Delta tables are different, and often do qualify.
**5. Where can I see Photon-on vs Photon-off DBU usage?**
In [`system.billing.usage`](https://docs.databricks.com/aws/en/admin/system-tables/billing#billable-usage-table-schema), split `usage_quantity` by `product_features.is_photon` to see how much of your spend ran with Photon versus without. It's most useful on jobs and pipelines you can actually toggle — SQL warehouses run Photon always-on, so there's nothing to compare there.
---
## LakeSentry Is Now Available as a Databricks App
- URL: https://lakesentry.io/blog/lakesentry-databricks-app-marketplace/
- Published: 2026-06-23
- Author: LakeSentry Team
- Category: product
- Tags: lakesentry, databricks, databricks-app, marketplace, lakebase
> LakeSentry, the cost observability platform for Databricks, is now available as a native Databricks App on the Marketplace. What it means, and where it runs.
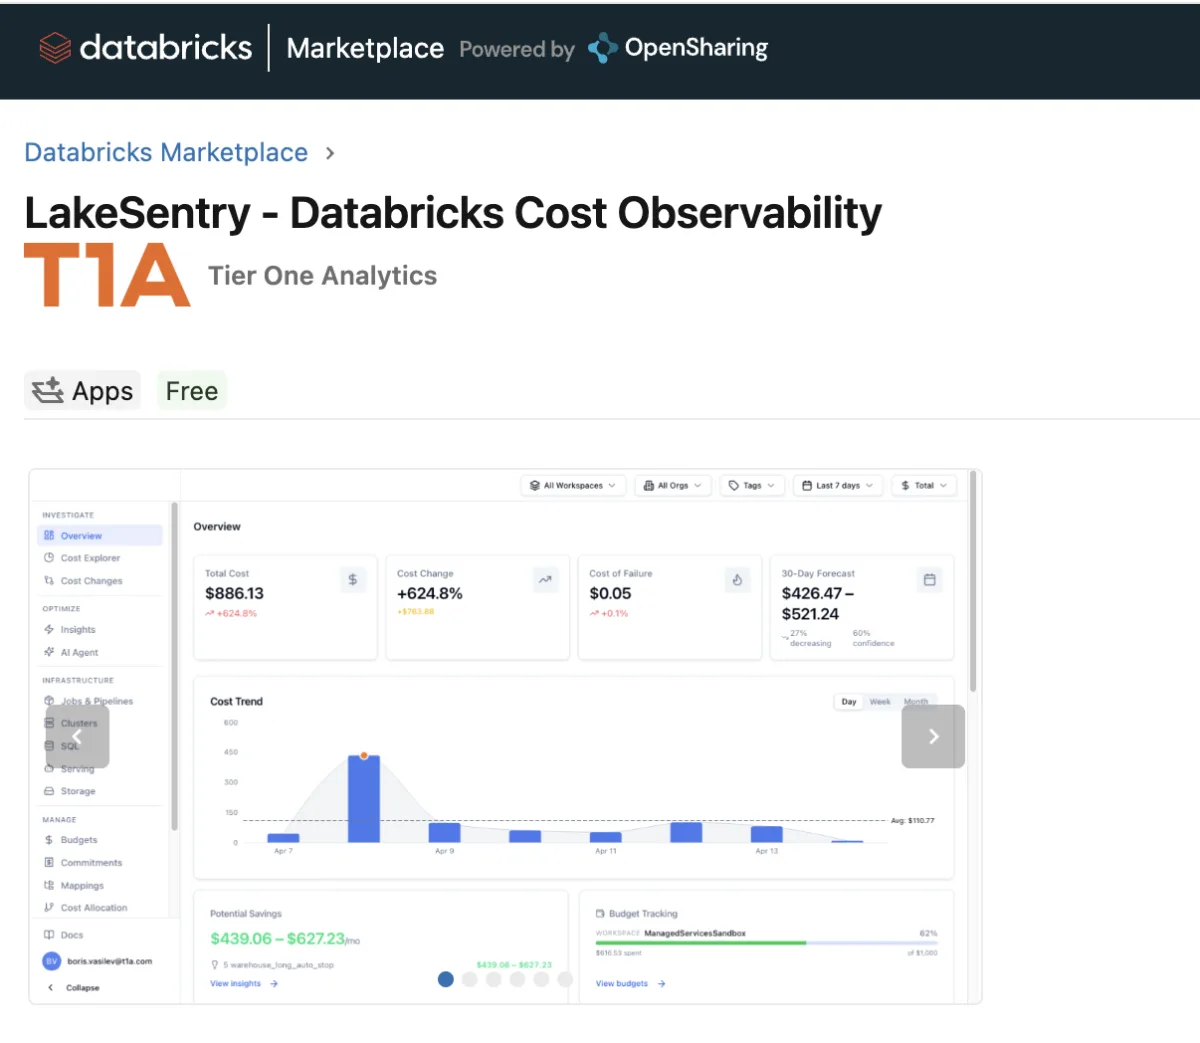
LakeSentry is now a native **Databricks App**, installable straight from the [Databricks Marketplace](https://marketplace.databricks.com/details/7700a2dd-b649-428c-9758-eeeadf9b90cc/Tier-One-Analytics_LakeSentry-Databricks-Cost-Observability). Databricks [opened the Marketplace to third-party apps](https://www.databricks.com/blog/announcing-apps-databricks-marketplace) at Data + AI Summit 2026, and LakeSentry was one of the launch apps.
LakeSentry gives Databricks teams cost observability: it attributes spend across workspaces, flags cost anomalies before the invoice does, and surfaces what to optimize. As a Databricks App, all of it now runs inside your own account.
LakeSentry on the Databricks Marketplace.
## Built on Databricks, Running in Your Account
LakeSentry runs entirely on the Databricks Apps runtime, in your own workspace. Its backend is PostgreSQL, so it keeps its cost ledger in a [Databricks Lakebase](https://www.databricks.com/product/lakebase) database you own and govern under Unity Catalog. Usage data, query text, and credentials never leave your account. The only thing that does is a periodic license check.
That makes it a clean fit for teams that need their cost data to stay in their environment, often to clear a security review. The attribution, anomaly detection, and optimization are identical to our [hosted SaaS](/); only the boundary moves.
## Get Started
Install LakeSentry from the [Databricks Marketplace](https://marketplace.databricks.com/details/7700a2dd-b649-428c-9758-eeeadf9b90cc/Tier-One-Analytics_LakeSentry-Databricks-Cost-Observability), or see the [LakeSentry Databricks App page](https://lakesentry.io/databricks-app/) for the architecture and a step-by-step install. Cost observability — now native to Databricks.
---
## Databricks Observability for Cost Drift and Spikes
- URL: https://lakesentry.io/blog/databricks-observability/
- Published: 2026-06-04
- Author: kristina-kazmina
- Category: cost-optimization
- Tags: databricks, observability, cost-monitoring, system-tables, platform-engineering
> What Databricks system tables tell you, what they don't, and how to build a cost monitoring layer that catches anomalies before someone opens a ticket.
Databricks observability is the practice of measuring DBU spend at the resolution of *who*, *what*, and *why* — not just yesterday's total across the account. It tells you which team owned a cost spike, whether a tripled job duration is the start of a retry storm or a seasonal blip, and why three SQL warehouses have been idling since the engineer who set them up left in March. The native console answers the totals question well; observability is what fills in the rest, and most teams only notice the gap once a bill has already moved.
One scope note first: this post is about Databricks *service* cost — the DBUs you're billed for jobs, SQL, and serverless compute. It isn't about the underlying cloud-infrastructure bill (the VMs, storage, and network your cloud provider charges separately). The two move together, but the system tables, queries, and patterns below all measure the Databricks layer.
## The Native Observability Primitives
Before building anything on top, it helps to inventory what Databricks already ships as observability *primitives*. There are five, and the gap is in how they fit together, not in whether they exist.
| Native tool | What it shows | What it doesn't |
|---|---|---|
| **Account Usage dashboard** | DBU spend by workspace and SKU, account-level totals | Per-team attribution, cross-region rollup |
| **System tables** ([Unity Catalog](https://docs.databricks.com/aws/en/admin/system-tables/)) | Per-cluster, per-job, per-warehouse usage rows over a rolling 365-day window | Anything outside the metastore's region |
| **Cluster compute metrics UI** | Per-cluster CPU, memory, disk, network (DBR 13.3+) | Long-range trends, cross-cluster comparison |
| **[Budget alerts](https://docs.databricks.com/aws/en/admin/account-settings/budgets)** (Public Preview) | Email when spend crosses up to four fixed thresholds | "Something is off" signals; only crossings |
| **Databricks SQL Alerts** | Scheduled queries on any table; notifies via email, webhook, Slack, PagerDuty | Anomaly logic; you write it |
System tables are the practical foundation. The cost-relevant ones — `system.billing.usage`, `system.compute.clusters`, `system.compute.warehouses`, `system.lakeflow.jobs` — retain a rolling 365-day window inside one Unity Catalog metastore. The join chain that ties them together is in the dashboard section below.
Budget alerts handle the "we crossed a number" case. They notify on up to four thresholds against a budget envelope and filter by workspace, team, or tag. They don't say *why* the threshold was crossed — and they price every DBU at SKU list rate, so the dollar figure ignores any negotiated discount your account has.
The piece most teams reach for next is Databricks SQL Alerts. Schedule a query against `system.billing.usage`, set a condition, route to Slack. That works for known patterns. Defining the condition is still your job.
## The Gap: Monitoring vs Observability
The shorthand most platform engineers already use is: monitoring tells you *what happened*; observability tells you *why, and what to do about it*. For Databricks specifically, the gap shows up in three places.
**Cross-workspace normalization.** A platform with five workspaces gets five separate per-workspace usage views. System tables let you query across, but only within one Unity Catalog metastore, and metastores are per-region. Teams that span US-East and EU-West get two queries (each in a different workspace), not one.
**Normalized units.** Photon DBUs, serverless DBUs, and classic-jobs DBUs aren't priced the same. Comparing usage volumes without weighting by per-DBU rate hides where the real spend is. Native tools don't normalize for you.
**Trend detection.** Budget thresholds catch crossings, not drift. A workload whose nightly run quietly doubled in cost over six weeks won't cross a monthly threshold until the seventh week. By that point you've paid for the first six. This is the most expensive blind spot in the native stack, and the one no built-in tool covers. Databricks does ship an "anomaly detection" feature, but it lives in [Lakehouse Monitoring](https://docs.databricks.com/aws/en/lakehouse-monitoring/data-quality-monitoring) and targets data quality (table freshness, completeness), not DBU spend. And because it runs on serverless compute, the monitoring itself adds to your DBU bill.
Observability is the layer that closes those three gaps. It's the discipline of treating cost telemetry the way you'd treat production telemetry: instrumented, queryable, normalized, alerted on patterns instead of fixed numbers. For most platform teams, this sits next to whatever dataops observability stack already runs for ingestion latency and pipeline freshness.
## Building a Cost Monitoring Dashboard with System Tables
The practical path for most teams starts with system tables and a dashboard.
The build sits on one join chain. Start from `system.billing.usage` (one row per billable DBU window, with `cluster_id` / `job_id` / `warehouse_id` inside the `usage_metadata` struct). Join `system.billing.list_prices` on `sku_name` for the per-DBU rate. Join `system.compute.clusters`, `system.compute.warehouses`, and `system.lakeflow.jobs` on the matching ID to attach the human-readable name of whatever ran. Multiply `usage_quantity` by the list price for dollars; pull `custom_tags['team']` (or your team-tag key) for per-team attribution.
From there, the dashboard you build depends on what questions matter first. Most teams start with three views:
- **Spend by team or environment over time.** Requires tags set consistently when clusters and jobs are created. If tagging isn't consistent across the environment, this view is where the gap shows up.
- **Top movers week-over-week.** Clusters, jobs, and warehouses with the largest absolute or percentage change in DBU consumption versus the prior comparable period.
- **Idle and orphaned compute.** Warehouses with high auto-stop minutes and low actual usage; clusters running past business hours with no job runs attached.
The honest limit is maintenance. System tables ship schema changes (the Lakeflow rename is one), and queries break quietly. The 365-day retention is a hard ceiling — year-over-year comparisons need you to archive earlier.
The other limit is that a dashboard is a pull tool — you only see the anomaly when you open the page. SQL Alerts solve the push half (schedule the query, route the result), but you still write the condition. Static thresholds catch step changes, not drift.
## Catching Cost Spikes and Slow Drift Before They Compound
The cost anomalies that hurt aren't the visible spikes. A sudden cost spike — a backfill that consumed 5x the DBUs of a normal run — gets caught fast because it crosses any reasonable threshold. The dangerous ones are slow. They don't trigger a threshold until weeks of damage have already happened.
Three patterns are worth knowing because they show up across most Databricks environments.
**The retry storm.** For streaming workloads, Databricks recommends running them as a [continuous job](https://docs.databricks.com/aws/en/jobs/continuous), which retries the whole job on failure with exponential backoff and no retry limit — regular jobs cap retries at a number you set, continuous ones don't. If the underlying failure is permanent (a missing permission, a renamed table, a downstream service returning 429s), the job retries indefinitely until someone notices the bill or the failure log. Two weeks of silent retries can double a workload's monthly cost before any threshold trips.
**The forgotten warehouse.** SQL warehouses have a minimum auto-stop (10 minutes for classic and pro, 5 minutes for serverless via the UI, 1 minute via the API), but the *default* a platform team picks during setup often isn't the minimum. A warehouse with `auto_stop_minutes = 240` that serves one Tableau dashboard running three queries a day pays for roughly four hours of idle compute per query. Multiply by the number of dashboards in the org and the math gets uncomfortable.
**The autoscaling drift.** Someone investigates a slow nightly job, bumps `max_workers` from 8 to 32 to clear the backlog, leaves it that way. Next quarter the data volume catches up and the job naturally scales toward 32 workers on every run, not just the busy ones. Nothing failed. Nothing alerted. The unit cost per run drifted up and stayed there.
Static thresholds miss all three patterns because they're not crossings, they're drift. The observability layer that catches them looks at change relative to that workload's own baseline: a job whose seven-day rolling cost is 2x its trailing-30-day median; a warehouse whose idle-hours ratio crossed 80% for the first time this quarter; a cluster whose average worker count has been climbing for three weeks. This is what teams typically build outside the native stack, usually because that's where it has to live.
## From Monitoring to Action
Observability without a response path is expensive logging.
The pattern that works in most platform teams has four steps:
1. **Alert.** A signal lands in a channel a human reads (Slack, email, PagerDuty).
2. **Investigate.** The signal points at one specific workload, with enough context to skip the "who owns this?" round-trip.
3. **Decide.** Kill, throttle, route to owner, or accept and document.
4. **Act.** Then close the loop so the signal stops firing.
Step 2 breaks most often. An alert that says "spend up 18% in workspace-prod" sends the on-call into a 90-minute spelunking trip through the logs. One that says "job `nightly_etl_v2` averaged $340/run this week vs $120 trailing-30-day median, owned by team `data-platform`" turns into a five-minute ticket.
> Most cost problems are obvious once they're visible. The hard part is getting the signal to the right person while the bill is still recoverable.
Teams rarely discover an intricate cost story — they discover a job nobody owned, a warehouse nobody remembered, a config that drifted while the people who set it up moved teams.
## Wrapping Up
Databricks observability isn't a dashboard you build once. New teams spin up workspaces, new jobs get scheduled, old ones get forgotten — the system that watches the platform needs to keep up with the platform itself. The native stack gives you most of the raw signals; the question is whether you build the layer above it or pick it up already built. For the conceptual frame on where each native signal lands, see the [native cost tools post](https://lakesentry.io/blog/native-databricks-cost-tools/).
## FAQ
**1. Which Databricks system tables show cost data?**
The primary cost table is `system.billing.usage`: every billable usage row with workspace, SKU, cluster/job/warehouse IDs, and timestamps. Join `system.billing.list_prices` for dollar amounts. Join `system.compute.clusters`, `system.compute.warehouses`, and `system.lakeflow.jobs` (renamed from `system.workflow.jobs` when Databricks rebranded [Workflows to Lakeflow Jobs](https://docs.databricks.com/aws/en/jobs/)) for the enhanced "what ran on what" picture. All require Unity Catalog and are scoped to one metastore per region.
**2. What's the difference between Databricks monitoring and observability?**
Monitoring tells you what you spent. Observability tells you why it changed, who owns it, and what's normal for that workload. For Databricks specifically, observability adds three things the native stack doesn't: cross-workspace and cross-region rollup, normalization across DBU types (Photon, serverless, classic), and pattern-based detection that catches drift instead of just threshold crossings.
**3. Does Databricks have built-in cost anomaly detection?**
Not for spend. Databricks ships [budget alerts](https://docs.databricks.com/aws/en/admin/account-settings/budgets) that fire on up to four fixed thresholds, and Lakehouse Monitoring offers "anomaly detection," but that feature targets data quality (table freshness, completeness), not DBU consumption. Pattern-based detection on spend (a job whose cost doubled relative to its own baseline) isn't native. Most teams build it on top of system tables.
**4. How long do Databricks system tables keep data?**
The cost-relevant system tables (`system.billing.usage`, `system.compute.clusters`, `system.compute.warehouses`) retain a rolling 365-day window. Year-over-year comparisons need you to archive earlier — the legacy CSV billing export is still available, though Databricks now points users toward system tables as the primary path.
**5. Does this apply to Azure Databricks and Databricks on GCP?**
Yes, for the Databricks service layer this post covers. Azure Databricks cost monitoring and Databricks-on-GCP cost monitoring use the same building blocks: identical system table schema, identical budget alerts, identical SQL Alerts. The differences are at the edges — availability timeline for some features, instance type naming, the storage backend for the legacy CSV billing export. The underlying cloud-infrastructure bill (VMs, storage, egress) is where the clouds genuinely diverge, and that sits outside the DBU layer this post measures.
In LakeSentry, the three layers this post describes (cross-workspace rollup, normalized DBU units, baseline-relative anomaly detection) are the default. Free tier connects an account and surfaces what the native tools don't show, no card required.
---
## Databricks Pricing: DBU Rates for AWS, Azure and GCP
- URL: https://lakesentry.io/blog/databricks-pricing-explained/
- Published: 2026-06-03
- Updated: 2026-10-01
- Author: LakeSentry Team
- Category: cost-optimization
- Tags: databricks, pricing, dbu, cost-optimization, finops
> Databricks pricing is per DBU: most compute runs $0.15 to $0.95 per DBU at Premium list rates. Rates by compute type for AWS, Azure and GCP, side by side.
Databricks pricing is **consumption-based**: you pay per DBU (Databricks Unit), metered per second, at a rate set by compute type, plan tier, cloud, and region. At September 2026 Premium list rates in US East regions, classic jobs compute on AWS bills $0.15 per DBU and all-purpose compute $0.55; the table below covers every compute type on all three clouds. Classic compute also puts the VMs on your cloud bill, while serverless rates include the compute; storage and networking come from your cloud provider either way. This guide explains the Databricks pricing model — how tiers and clouds change the number, and the costs the pricing calculator won't show you.
While the model is simple on paper, in practice, it can often become confusing when trying to explain costs of specific workloads — for instance, the difference in cost for the same SQL query can change significantly depending on the type of warehouse used to execute it.
## What a DBU Is and How You're Billed
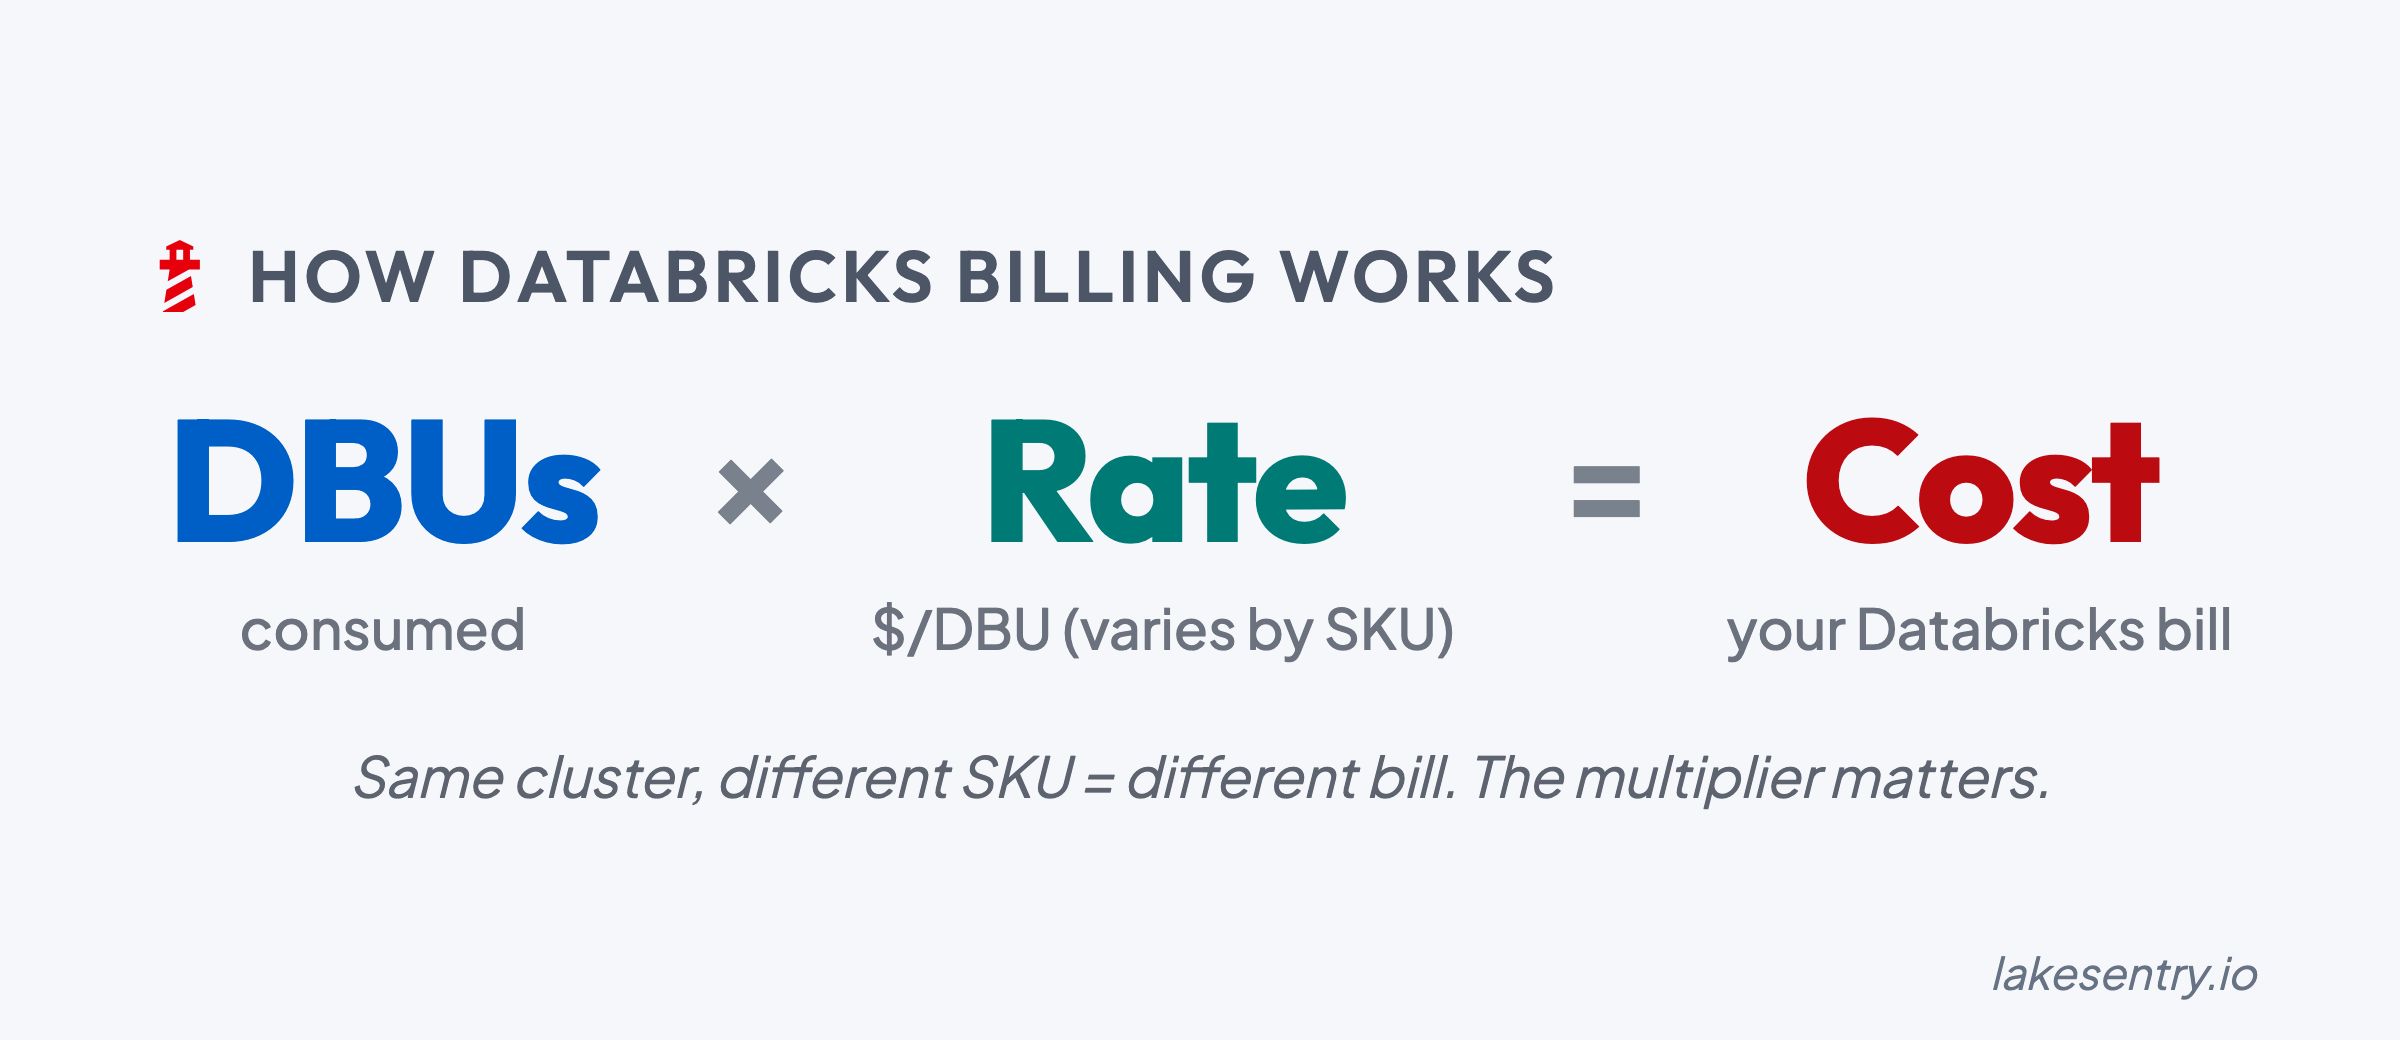
A DBU is a normalized unit of processing capability that Databricks meters per second of use. It is not a fixed amount of CPU or memory; it's a billing unit whose consumption depends on multiple factors, such as cluster instance type. Your DBU cost for any workload is DBUs consumed times the per-DBU rate for that workload's SKU.
The important part, as stated above, is that the full bill has two layers. Databricks meters DBUs. Your cloud provider (AWS, Azure, or GCP) separately bills the VMs, storage, and networking the workload ran on.
A migration that moves workloads from classic compute to serverless can look like "DBUs up, infrastructure down" while total spend barely moves — because serverless SKUs fold the infrastructure into a single, higher DBU rate. For the deeper mechanics of how DBUs meter, see the [DBUs explained](https://lakesentry.io/blog/databricks-dbu-explained/) post.
## DBU Rates by Compute Type
Different compute types bill at different per-DBU rates, and the spread is wide. Jobs compute is the cheapest classic SKU on AWS and GCP, while all-purpose (interactive) compute is the most expensive; SQL and serverless sit in between or above. The list rates below are Premium tier, US dollars per DBU, in each cloud's US East region (AWS N. Virginia, Azure East US, GCP Virginia), as of September 2026 ([Databricks pricing](https://www.databricks.com/product/pricing), [Azure Databricks pricing](https://azure.microsoft.com/en-us/pricing/details/databricks/)). On Azure, Premium corresponds to the Enterprise tier on AWS and GCP. Rates change over time and by region, so treat them as the shape of the model rather than a quote.
| Compute type | AWS | Azure | GCP |
|---|---:|---:|---:|
| Jobs Compute (Lakeflow Jobs Classic) | $0.15 | $0.30 | $0.15 |
| Lakeflow Declarative Pipelines (Core) | $0.20 | $0.30 | $0.20 |
| SQL Classic | $0.22 | $0.22 | $0.22 |
| Serverless jobs and pipelines | $0.35 | $0.45 | $0.35 |
| All-Purpose Compute | $0.55 | $0.55 | $0.55 |
| SQL Pro | $0.55 | $0.55 | $0.55 |
| SQL Serverless | $0.70 | $0.70 | $0.70 |
| Serverless notebooks | $0.75 | $0.95 | $0.75 |
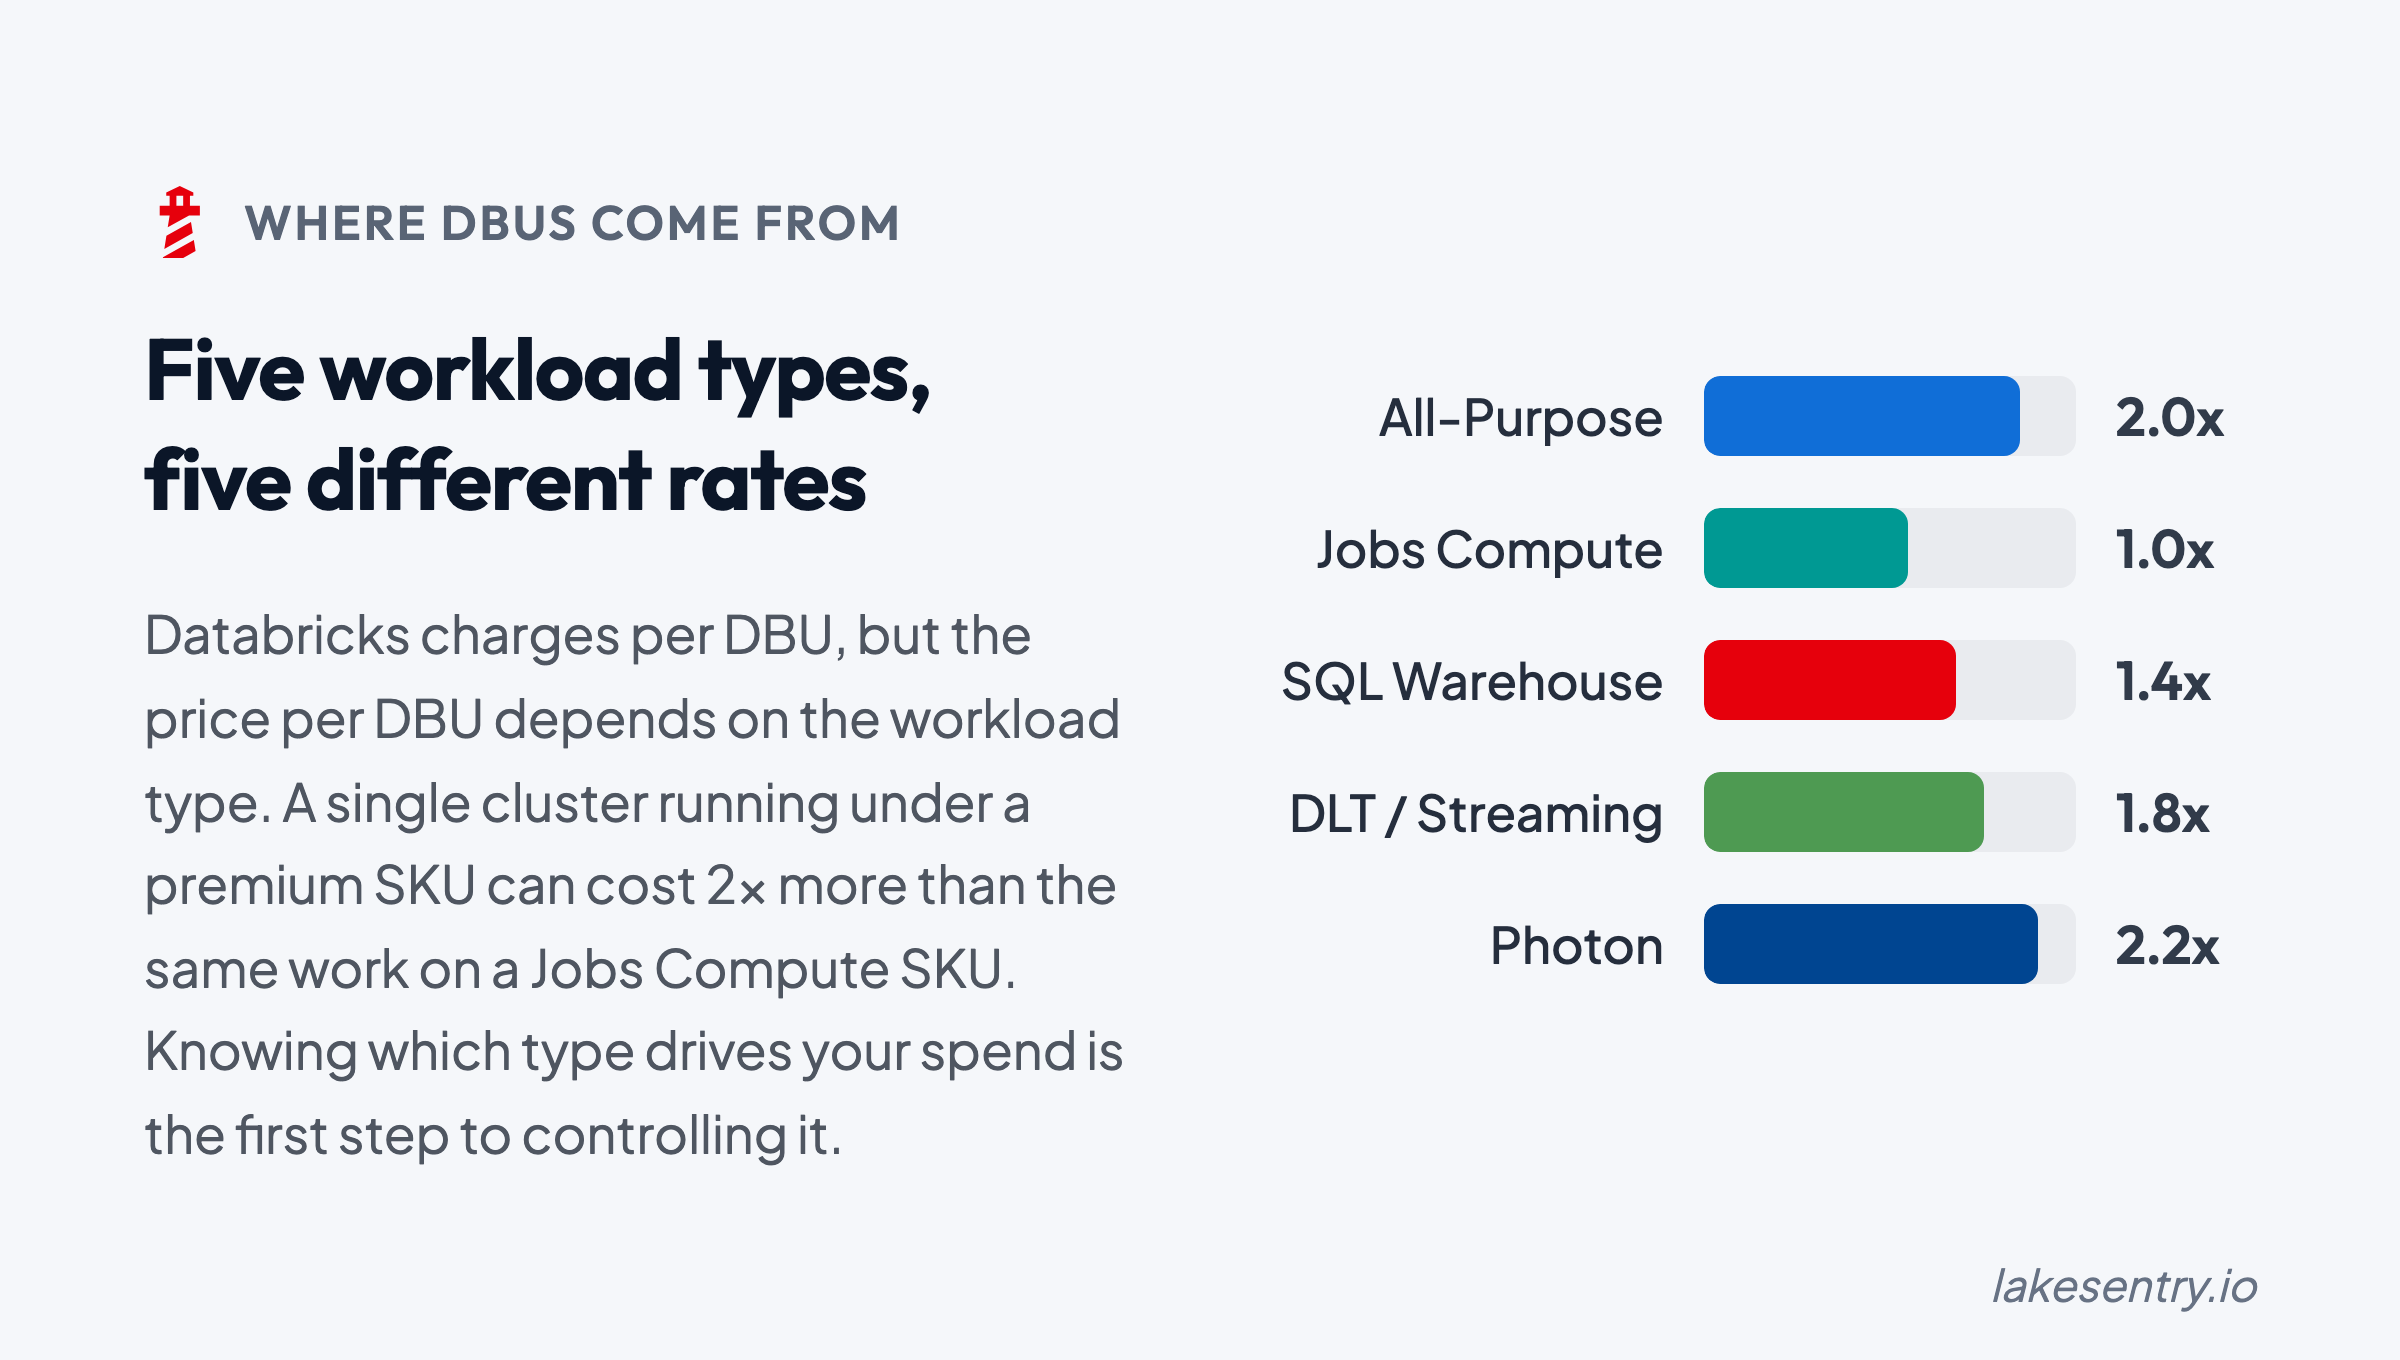
On AWS and GCP, all-purpose compute runs at roughly three to four times the rate of jobs compute (about 1.8x on Azure, where jobs compute lists at $0.30), which is why scheduled work that quietly lands on an interactive cluster is such an easy source of cost to miss ([all-purpose vs jobs compute](https://lakesentry.io/blog/databricks-all-purpose-vs-jobs-compute/)). Note the product names: what many still call Databricks Workflows is now Lakeflow Jobs, and Delta Live Tables is now Lakeflow Declarative Pipelines. The classic billing SKUs still carry the older prefixes, which is why both names show up in cost data.
Serverless rates need a caveat when you compare them. SQL Serverless at $0.70 looks far above SQL Classic at $0.22, but the serverless number folds in the cloud VM cost that classic compute bills separately on top of its DBU rate. Comparing a serverless $/DBU against a classic $/DBU is not like-for-like. The honest comparison is total cost, DBUs plus the separate infrastructure line, and on bursty workloads serverless often comes out ahead despite the higher headline rate.
Lakebase, the managed Postgres database, is priced per capacity-unit hour (converted to DBUs on your bill); see [Lakebase pricing](https://lakesentry.io/blog/databricks-lakebase/) for its rates on each cloud.
## Pricing Tiers: Standard, Premium, Enterprise
Your plan tier multiplies every rate above. Databricks plans run Standard, Premium, and Enterprise, though Azure has now retired its Standard tier and per-cloud availability differs (see the cloud sections below). Higher tiers cost more per DBU and add governance, security, and compliance features.
One tier fact matters for cost tooling specifically: Unity Catalog requires the Premium plan or above, and it is enabled by default on workspaces created since late 2023 ([Unity Catalog setup](https://docs.databricks.com/aws/en/data-governance/unity-catalog/setup-uc)). That's relevant because the system tables you use to track cost live in Unity Catalog. If you're on a Standard workspace, the detailed usage data isn't available until you move up. Azure retired its Standard tier on October 1, 2026, so most new environments start at Premium regardless.
## Why Cost Differs by Cloud and Region
The same compute type costs different amounts on AWS, Azure, and GCP — and within a cloud it varies by region. DBU rates are set per cloud, and the underlying VM prices that sit beneath classic compute follow each cloud's own regional pricing.
### Azure Databricks Pricing
Azure Databricks is a first-party Azure service, so DBUs bill through your Azure subscription at rates Microsoft publishes on the [Azure Databricks pricing page](https://azure.microsoft.com/en-us/pricing/details/databricks/). The underlying VMs follow Azure's own regional rate card. Azure's plan tiers were Standard and Premium until the Standard tier reached end of life on October 1, 2026: new workspaces have had to use Premium since April 1, 2026, and Standard workspaces still running on October 1 are upgraded to Premium automatically ([Microsoft Learn](https://learn.microsoft.com/en-us/azure/databricks/admin/account-settings/standard-tier)).
### AWS Databricks Pricing
On AWS, Databricks sets the DBU rates ([AWS pricing](https://www.databricks.com/product/aws-pricing)) while AWS bills the EC2 instances, EBS storage, and data transfer separately underneath. AWS offers the Premium and Enterprise tiers, and per-DBU rates vary by region alongside EC2 pricing.
### GCP Databricks Pricing
On Google Cloud, Databricks publishes its own [GCP DBU rates](https://www.databricks.com/product/gcp-pricing) while Google bills the Compute Engine VMs and storage. GCP runs on the Premium tier, with the same compute-type rate spread; the difference is the underlying GCE rate card and regional availability.
> "How much does Databricks cost?" has no single answer because the rate depends on compute type, tier, cloud, and region all at once.
This is why a number someone quotes from a blog post or a proposal rarely matches your bill. The model is consistent — the inputs are specific to your setup.
## The Pricing Calculator and What It Misses
Databricks publishes an official [pricing calculator](https://www.databricks.com/product/pricing/product-pricing/instance-types) that multiplies an estimated DBU consumption by the rate for a compute type and tier. It's useful for a first estimate and for comparing SKUs. What it can't do is predict how your environment behaves.
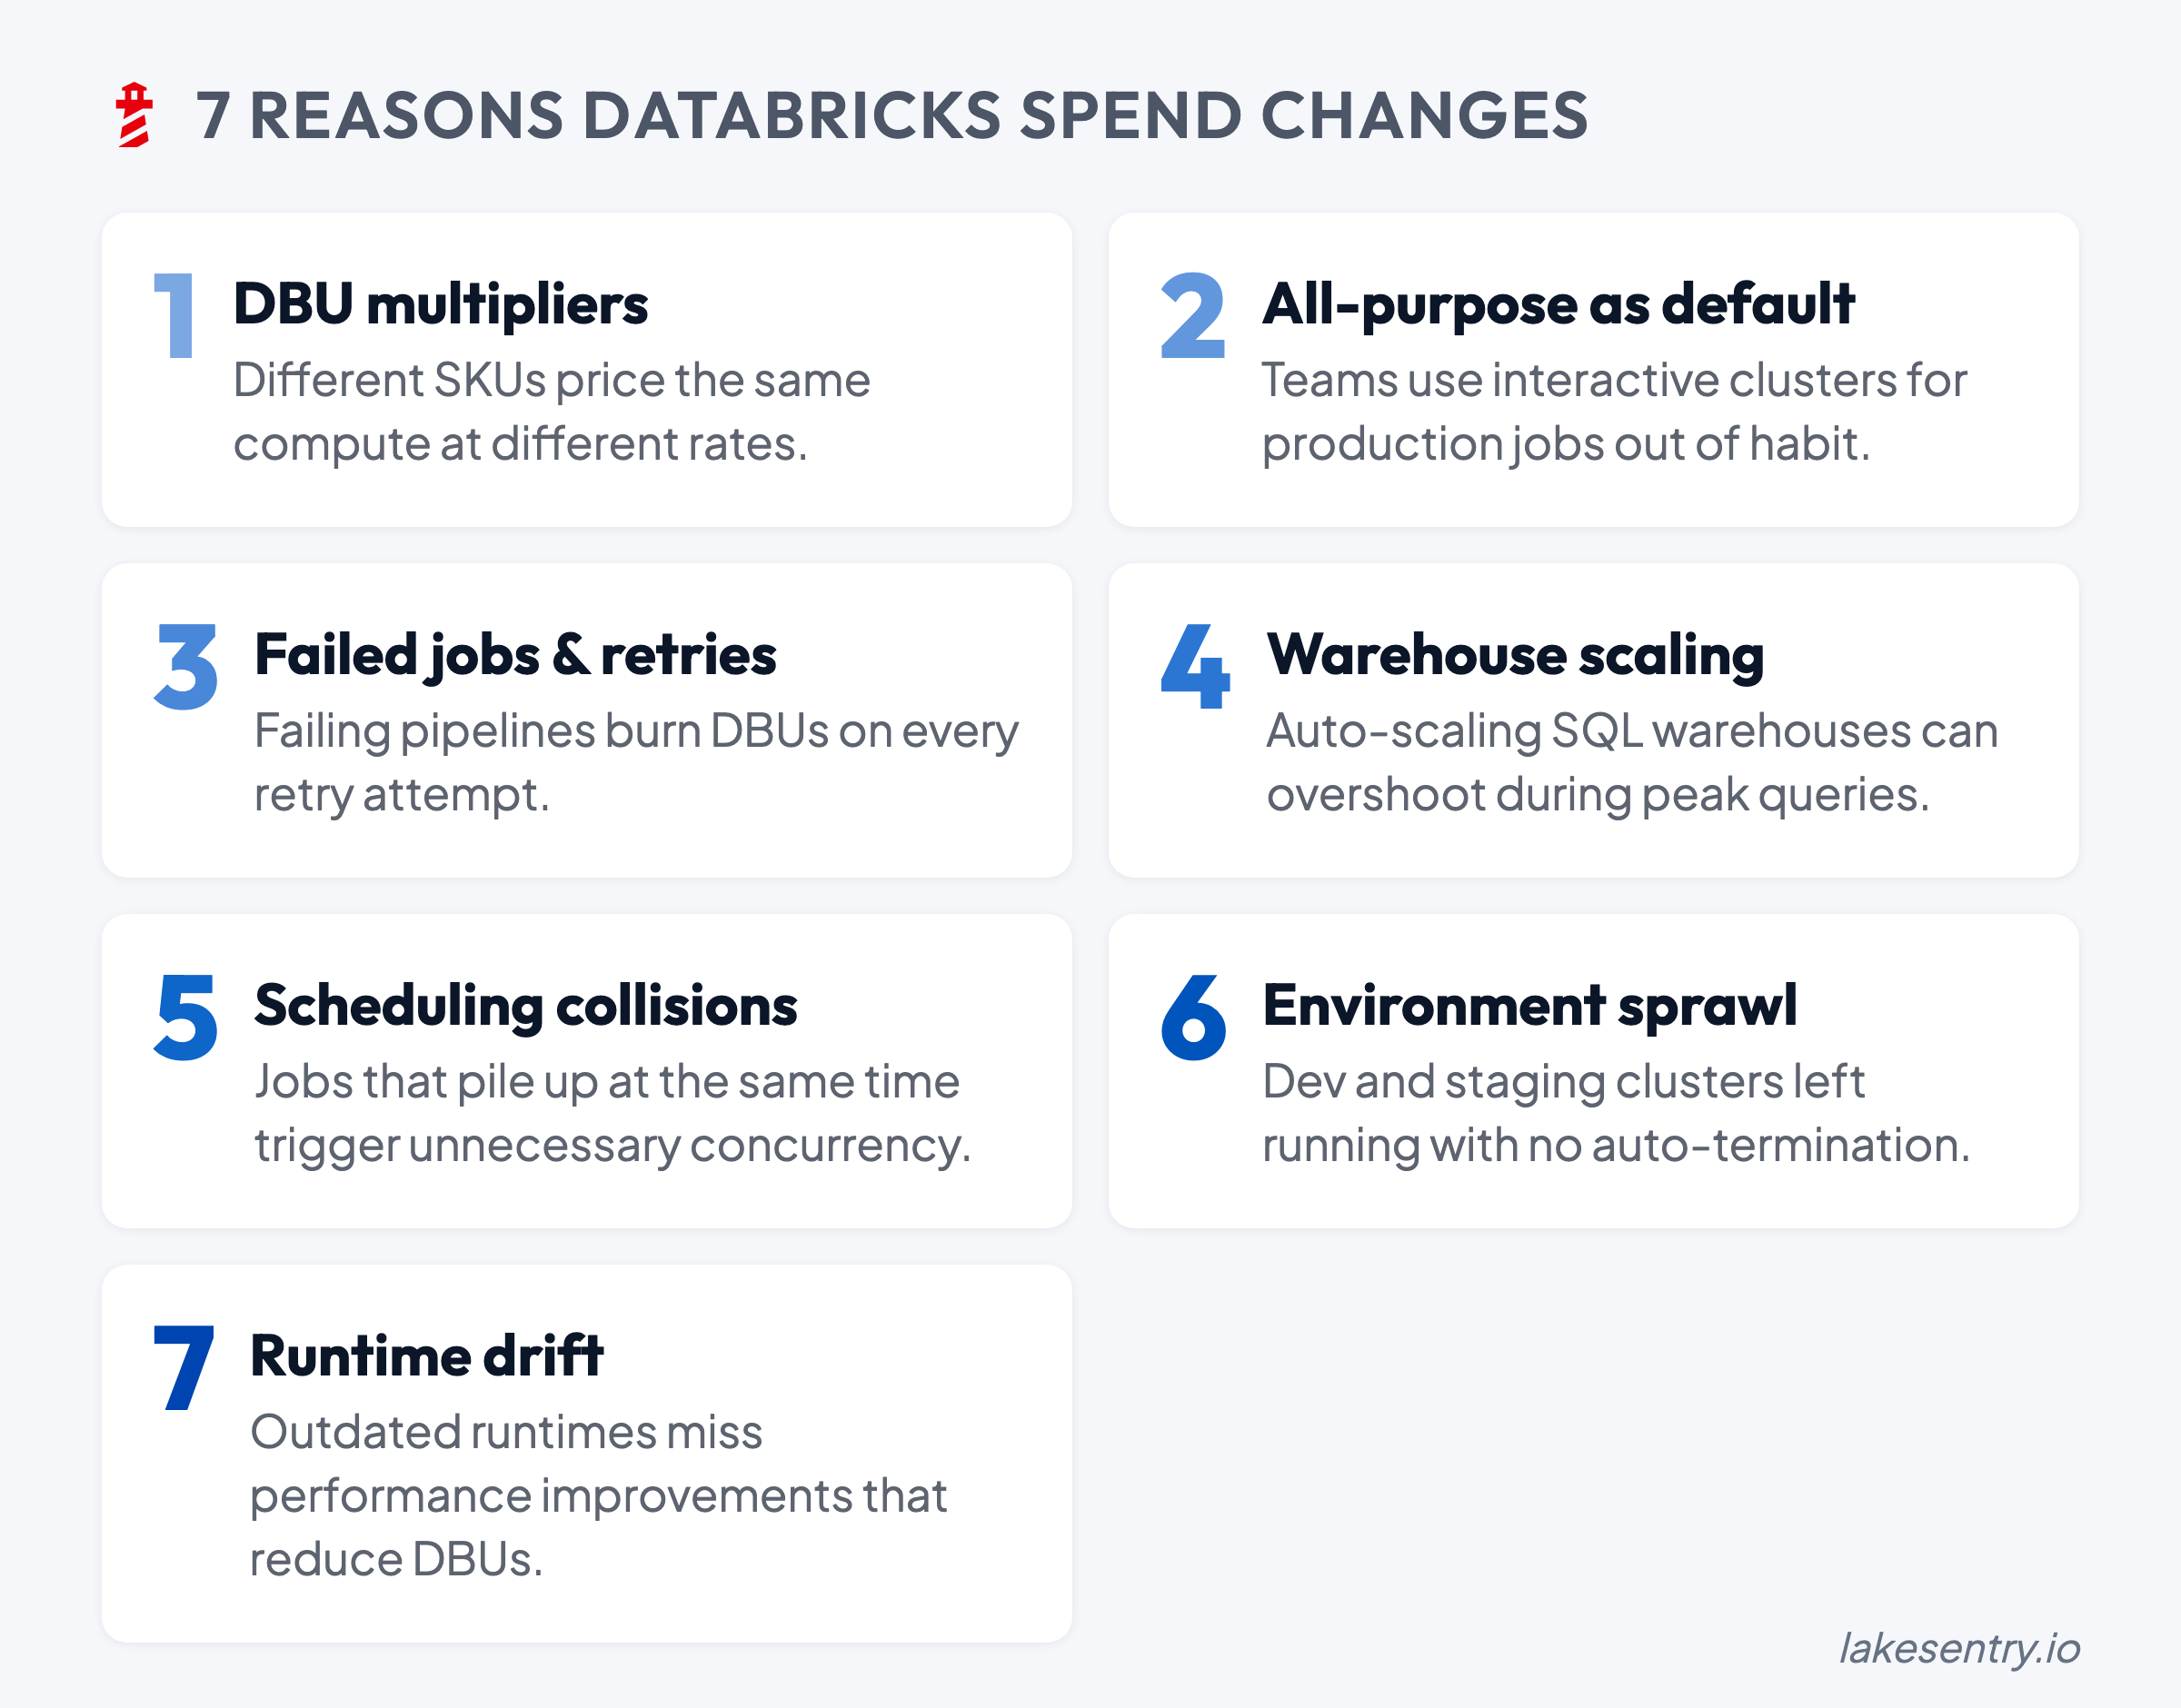
The calculator assumes a clean consumption number. Real environments add autoscaling that overshoots and holds extra nodes, clusters that idle between runs at the full rate, and jobs that fail and retry, re-paying startup each time. None of those show up in an estimate. The gap between the calculator and the invoice is almost always in the environment behavior.
Our [Databricks cost calculator](https://lakesentry.io/databricks-cost-calculator/) starts from the workloads instead — you describe what you run, and it estimates the bill including the behavior layer.
## Hidden Cost Drivers Teams Discover Late
Most pricing surprises come from a handful of drivers that the rate card doesn't make obvious.
- **Photon.** Enabling [Photon](https://docs.databricks.com/aws/en/compute/photon) doesn't raise the price per DBU; it consumes more DBUs per hour because Photon-enabled nodes carry a higher DBU multiplier. On compute-bound work it finishes faster and can lower total cost; on work it can't accelerate, it just bills more per hour. Whether it pays off is a per-workload question.
- **Autoscaling overshoot.** Autoscaling adds nodes quickly and releases them slowly, so a brief spike can keep extra capacity billing long after the spike passes.
- **Idle compute.** An interactive cluster or a warehouse with a long auto-stop window bills at the full rate while doing nothing.
- **Storage is separate.** DBUs cover compute. Cloud storage and data transfer are billed by the cloud provider on top.
- **Commitments, not reserved instances.** Databricks discounts come from committed-use agreements (measured in DBCUs, Databricks Commit Units), not the "reserved instances" model you know from cloud VMs, which lower your effective rate below list.
Once a workload is running, the only source of truth is your own usage data. Databricks system tables record actual DBU consumption and the list rate for every line item, so you can reconcile what you were billed against what you estimated. The recurring lesson is that the surprises live in behavior, and behavior is what an estimate can't capture; for the wider playbook on acting on that data, see [Databricks cost optimization](https://lakesentry.io/blog/databricks-cost-optimization/).
Databricks pricing is predictable once you separate the model from the behavior. The rate card is straightforward. The surprises come from the gap between the model and how your environment runs day to day — such as shared clusters, autoscaling, idle time, Photon. Closing this gap is a visibility problem more than a pricing one.
## FAQ
**1. What is a DBU in Databricks?**
A DBU (Databricks Unit) is a normalized unit of processing capability, billed per second of use. The DBUs a workload consumes per hour depend on its instance type and node count, and the dollar rate per DBU depends on the compute type, tier, cloud, and region.
**2. How much does Databricks cost per DBU?**
It depends on the compute type and plan. For instance, a rough AWS Premium guide for September 2026: jobs compute around $0.15, SQL Classic around $0.22, all-purpose around $0.55, and SQL Serverless around $0.70 per DBU.
**3. Why is all-purpose compute so much more expensive than jobs compute?**
All-purpose (interactive) compute is the priciest classic SKU because it's built for shared, interactive sessions. It runs roughly three to four times the jobs-compute rate on AWS and GCP (about 1.8x on Azure), so scheduled work placed on it by accident is a frequent, easily-missed cost.
**4. Does Photon increase the DBU rate?**
No. Photon keeps the same price per DBU but consumes more DBUs per hour. It lowers total cost only when the speedup outweighs the extra consumption, which depends on the workload.
**5. Why doesn't the pricing calculator match my bill?**
The calculator estimates rate times a clean DBU number. Your bill reflects real behavior (idle time, autoscaling overshoot, retries), plus separately billed cloud infrastructure and any committed-use discount. Those gaps are where estimates and invoices diverge.
**6. Is Databricks cheaper on AWS, Azure, or GCP?**
There's no universal answer. Databricks sets DBU rates per cloud, and Microsoft, AWS, and Google each price the underlying VMs on their own regional rate cards. The cheapest option depends on your compute mix, region, and tier, so compare total cost (DBUs plus infrastructure) on your workloads, not headline rates.
---
LakeSentry shows your real effective rates and DBU usage across every connected workspace, reading only system-table cost metadata, never your business data, notebooks, or query results. Free tier, no card.
---
## Databricks All-Purpose vs Jobs Compute: When to Use Which
- URL: https://lakesentry.io/blog/databricks-all-purpose-vs-jobs-compute/
- Published: 2026-05-29
- Updated: 2026-10-01
- Author: LakeSentry Team
- Category: compute-fundamentals
- Tags: databricks, compute, dbu, cost-optimization, platform-engineering
> Job cluster vs all-purpose cluster in Databricks: all-purpose bills about 2–4x the jobs-compute DBU rate. When each fits, and how to see which your jobs run on.
All-purpose compute in Databricks is built for interactive, multi-user work — notebooks, ad-hoc analysis, shared exploration. Jobs compute is built for scheduled, automated runs of known code. All-purpose is priced at roughly 2–4x the DBU rate of jobs compute ([Databricks pricing](https://www.databricks.com/product/pricing)), so when scheduled work ends up on all-purpose by accident, the bill grows quietly — though, as we'll get to, all-purpose for jobs is the right call in some cases.
## What all-purpose and jobs compute are
You'll also see them called all-purpose clusters and job clusters: the classic versions of each compute type, which run in your own cloud account. Serverless options are covered further down. The two compute types look almost identical in the Databricks UI, which is part of why they get mixed up. They're not interchangeable.
**All-purpose compute** is a long-lived cluster you start manually (or via auto-start), attach a notebook to, and share with other users. It supports concurrent users, access to cluster-installed packages, and stays running until you stop it or auto-termination kicks in. It's the default when you create a notebook and click "Run." It can also be used for scheduled workloads.
**Jobs compute** is a cluster Databricks creates for a specific job run and shuts down once the run completes. The cluster is dedicated to that one job and stops billing the moment the job ends — it isn't shared with other users, and its state doesn't persist between runs.
The Spark engine and runtime version are the same as on an all-purpose cluster, and the code that runs is identical. What changes is the cluster's lifecycle and the per-DBU rate Databricks charges.
## Why the cost differs
Databricks bills by [DBU](https://lakesentry.io/blog/databricks-dbu-explained/) consumption × [per-DBU rate](https://lakesentry.io/blog/databricks-pricing-explained/). The rate is set by SKU, and the SKU is determined by the workload type.
All-purpose has the highest per-DBU rate because it's optimized for interactivity — concurrent users, notebook attach/detach, long-running sessions, hot data caches. Jobs compute is the cheapest classic SKU because it does one thing and exits.
The exact ratio depends on plan tier and cloud provider: at Premium list rates it's about 3.7x on AWS and GCP ($0.55 vs $0.15 per DBU) and about 1.8x on Azure, where jobs compute lists at $0.30. On top of the DBU charge, the cloud provider bills the underlying VMs separately — that part is roughly the same for both compute types.
## When each compute type is the right fit
The decision is usually about *who* is running the work, what level of *workload isolation* it needs, and *whether the same code will run again on a schedule or trigger*.
### All-purpose: interactive and exploratory
Use all-purpose when:
- A human is at the keyboard, attaching a notebook, iterating on queries
- Multiple users need to share the same environment — library state, environment variables, services started via init script
- BI tools refresh on demand and need a warm cluster
The premium DBU rate buys interactivity. If nobody is iterating, you're paying for capability you don't use.
### Jobs compute: scheduled and repeatable
Use jobs compute when:
- The work runs on a schedule, a trigger, or a workflow step
- Each run is independent — no shared state between runs
- The cluster doesn't need to outlive the job
- Cluster state should stay workload-specific (e.g. library state isolation)
The savings come from two places: the lower per-DBU rate, and the fact that a job cluster can't sit idle between runs (with the exception of some streaming workloads, which include idle gaps by design). It exists for one run and terminates.
## Side-by-side at a glance
| | All-Purpose Compute | Jobs Compute |
|---|---|---|
| **Built for** | Interactive notebooks, ad-hoc code execution, BI refresh | Scheduled jobs, workflows, automated pipelines |
| **Lifecycle** | Long-lived; manual start, manual termination or auto-terminate after idle | Created per job run, destroyed on completion |
| **Concurrency** | Multiple users and workloads share one cluster | Single job, isolated |
| **Per-DBU rate** | Highest classic SKU | Lowest classic SKU (~2–4x cheaper) |
| **Idle cost** | Real — pays while no one is using it | None — cluster terminates with the job |
| **Right call when** | A human is iterating, or a large group of workloads runs at the same time and doesn't require isolation | A schedule or trigger is running known code and workload isolation is needed |
## How wrong-fit workloads show up
Most environments don't have a single "we use all-purpose for everything" problem. They have a long tail of automated work that ended up on all-purpose because that's where it was tested.
A few of the usual suspects:
- **Automated jobs pointed at an existing all-purpose cluster.** Databricks lets you point a scheduled, API-triggered, or workflow-driven job at an existing all-purpose cluster. Convenient during development, expensive in production — the cluster keeps running between runs unless you've configured aggressive auto-termination.
- **Shared "team clusters" hosting both interactive work and scheduled refreshes.** A long-running all-purpose cluster set up for the data team's notebooks ends up running scheduled jobs too — it's already up, and shared-cluster permissions are simpler than per-job access management.
- **Long auto-termination windows.** All-purpose clusters with `autotermination_minutes` set to 120, 240, or "never" are usually a relic of someone debugging once and not changing it back. The idle hours add up.
Across the Databricks environments we review at LakeSentry, the typical production pattern is most scheduled jobs running on jobs compute — though we still see teams using all-purpose compute in jobs, usually because permissions were easier on a shared cluster or serverless wasn't an option when the workload was first set up. Databricks' own guidance is that all-purpose isn't recommended for production jobs, so both setups are worth revisiting.
The reason these are hard to catch is that none of them look wrong in the top-level UI. The cost lens that shows compute type next to actual usage pattern is the one most native tools don't surface — see [Native Databricks cost tools vs. the cross-workspace view](https://lakesentry.io/blog/native-databricks-cost-tools/) for the longer take on that gap.
## SQL warehouses, serverless, and other compute
Two clarifications, because these don't fit the all-purpose / jobs binary.
**SQL warehouses** aren't clusters — they're a separate compute type with their own SKU, purpose-built for SQL analytics through BI tools and the SQL editor. Don't compare them directly to all-purpose; compare them to "would I otherwise put this BI query on an interactive cluster?" If yes, the warehouse usually wins on both cost and performance.
**Serverless compute** is a third path Databricks now offers — it removes cluster management entirely but uses a different DBU rate and cost model, so it isn't a direct comparison with classic compute. Rule of thumb: classic jobs compute is still cheapest at high, steady utilization; serverless wins for bursty workloads or when not managing clusters is the bigger value.
## FAQ
**Can I run a notebook on a job cluster?**
Yes — that's what a scheduled notebook job does when you point it at a new job cluster instead of an existing all-purpose one. The notebook runs end-to-end on the job cluster, which terminates when the run completes.
**What about SQL warehouses — do they replace either of these?**
For BI and SQL analytics workloads, yes — SQL warehouses are the right compute, not all-purpose. They're not a substitute for jobs compute running pipelines or for notebooks running Python.
**Is serverless cheaper than classic compute?**
Not by default. Serverless compute uses a different DBU rate and cost model than classic compute. For steady, high-utilization scheduled work, classic jobs compute is usually cheaper. Serverless wins when workloads are bursty (you pay per workload, not per cluster hour) or when avoiding cluster management itself has value.
**How do I know if my team is using the wrong compute type?**
The signal is per-cluster utilization: an all-purpose cluster that runs scheduled work and has long idle gaps, or a cluster with auto-termination set to multiple hours. The native console shows current state but not the pattern over time. Cross-workspace cost attribution that tags each workload with its compute type and usage pattern is what makes wrong-fit jobs visible.
In LakeSentry, this lives in [Cost Explorer's Compute Types view](https://docs.lakesentry.io/features/cost-explorer/) (DBU spend split by Jobs / All-Purpose / SQL across all connected workspaces), with long auto-termination windows and idle clusters surfaced automatically in [Insights & Actions](https://docs.lakesentry.io/features/insights-actions/).
---
## FinOps 101 for Databricks: Transparency First
- URL: https://lakesentry.io/blog/databricks-finops-101/
- Published: 2026-05-25
- Author: konstantin-polukhin
- Category: cost-optimization
- Tags: databricks, finops, cost-transparency, attribution
> FinOps for Databricks stalls when teams optimize before they can explain spend. Build transparency first: attribution, explainability, shared definitions.
Most teams jump to optimizing Databricks spend before they can explain what's driving it. That's where FinOps hits the ceiling.
## The Moment That Exposes the Gap
It starts the same way every time. Someone asks: "The Databricks bill went up. Can you explain why?" You pull a billing export. You eyeball the top clusters. You open a Slack thread. Later, you have a theory. Maybe it was that ML pipeline, maybe a warehouse that didn't scale down. Nobody's usually confident enough to act on it.
This is a FinOps moment. The practice either works here or it doesn't. And for most teams, it doesn't — because teams can see spend totals but can't answer what changed, why, and who owns it. That gap makes optimization slow, risky, and political.
## FinOps, in Plain Terms
[FinOps](https://www.finops.org/) (cloud financial operations) is a discipline. It's a collaboration model: engineering, finance, and platform teams making informed spend decisions together, on a regular cadence.
The framework has three pillars:
- **Inform** — visibility, allocation, shared definitions. Everyone sees the same numbers.
- **Optimize** — rate and usage adjustments. Rightsizing, commitments, workload tuning.
- **Operate** — governance and continuous improvement. The practice sustains itself.
The order is deliberate. Inform comes first. "63% of organizations have FinOps practices in place, but cost challenges persist" (Flexera 2026 State of the Cloud). Often because teams go straight to Optimize before Inform is working.
The FinOps Foundation's six guiding principles. Source: finops.org/framework/principles.
## The Gap Between Adoption and Results
FinOps adoption is high and 85% rank cost management as their number one cloud priority, for the fourth consecutive year.
And yet, from the practitioner side: 42% currently prioritize workload optimization, but only 25% expect that to hold in the next twelve months. The reason, in their own words: "We have hit the 'big rocks' of waste and now face a high volume of smaller opportunities that require more effort to capture" ([State of FinOps 2026](https://data.finops.org/)).
Organizations have the practice. They don't have the explainability to make it work at the next level.
## Why Databricks Is Harder
FinOps practices like tagging, reserved capacity, and rightsizing are well-established for basic cloud infrastructure.
Tag your EC2 instances, buy reserved capacity, rightsize VMs. Databricks adds structural complexity that breaks that playbook.
The bill has two layers. DBUs are metered by Databricks. VMs, storage, and networking are billed separately by your cloud provider. A serverless migration can look like "DBUs up, infra down" while total cost barely moved. You have to separate the layers before you can diagnose anything.
Within the DBU layer, rates differ by workload type. All-Purpose Compute, Jobs Compute, SQL Warehouses, serverless: each has a different multiplier. The same pipeline on different compute produces a different invoice line. Then add shared clusters where nobody can name an owner, retry storms that compound cost without showing up cleanly, and SQL warehouses that scale up on Monday and never come back down.
For the full breakdown, see [DBUs explained](https://lakesentry.io/blog/databricks-dbu-explained/) and [why Databricks spend changes](https://lakesentry.io/blog/databricks-spend-changes/).
## Transparency Before Optimization
Here is the core argument: optimization without transparency creates churn.
You cut something, can't tell if it helped, cut something else, break a pipeline, roll back, lose credibility. When Databricks spend is explainable (by workload, owner, and weekly deltas), optimization becomes engineering work: routine and measurable.
Cost transparency has three components:
- **Attribution:** every cost line has a team, project, and environment attached.
- **Explainability:** you can say why something moved, not just that it moved.
- **Shared definitions:** workloads, environments, and ownership map to the bill the same way for everyone looking at it.
Optimization (cheaper compute types, autoscaling tuning, schedule adjustments) depends on all three. Without attribution you don't know what to touch. Without explainability you can't tell whether a change helped, or just moved the cost to a different line item.
Think of it like reliability. A single uptime number doesn't help you fix an incident; you need signals broken down by service. Cost works the same way.
## A Simple Maturity Ladder for Databricks
This is descriptive, not prescriptive. You don't need Level 4 to be "good at FinOps." But knowing where you are tells you what to build next.
- **Level 0:** Totals only. You see the monthly invoice. When spend moves, the investigation starts from scratch.
- **Level 1:** Allocation basics. You can answer "who owns this?" for most of the bill.
- **Level 2:** Explainability. You track week-over-week deltas by workload. When spend shifts, you can name the driver.
- **Level 3:** Operational loop. There's a weekly review. Top movers get an owner and a disposition: expected, investigate, or act.
- **Level 4:** Continuous optimization. Changes happen inside the engineering workflow, measured against baselines.
Most of the pain sits between Level 0 and Level 2. That's the transparency gap.
## Why Transparency First: Three Practical Reasons
You answer faster when spend shifts. If data is attributed by workload and owner, the investigation starts from a shortlist.
You break less. If you don't know why a workload runs on All-Purpose Compute, you don't know what moving it will do downstream. Transparency tells you what you're touching.
You argue less. "That's not our spend" and "those clusters are necessary" are symptoms of missing attribution. Visible ownership and shared definitions take the argument out of the room.
## Start Small This Week
Four moves to get from Level 0 toward Level 2:
1. **Pick one ownership unit.** Team, project, or environment. Whichever your org already uses. No need to invent a new one.
2. **Build a top-drivers weekly view.** Spend by workload, top 5–10 movers.
3. **Review deltas, not totals.** A workload that costs the same every week isn't interesting. One that doubled is, even if it's small in absolute terms.
4. **Write down 2–3 guardrails before you optimize.** What can't break? Which SLAs are non-negotiable? This prevents the "we saved money but broke the pipeline" outcome.
---
If you want the "thermometer" view — what's actually driving spend by workload and owner — LakeSentry has a free tier. No card. Connect a workspace and see what's there.
It only reads Databricks system tables for usage and cost metadata. LakeSentry never accesses your business data, notebooks, or query results.
Comparing options? See the [Databricks cost tools comparison](https://lakesentry.io/compare/databricks-cost-tools).
---
## Databricks Cost Optimization: A Practical Guide
- URL: https://lakesentry.io/blog/databricks-cost-optimization/
- Published: 2026-05-06
- Updated: 2026-08-05
- Author: LakeSentry Team
- Category: cost-optimization
- Tags: databricks, cost-optimization, finops, guide, dbu
> Databricks cost optimization is matching compute and warehouses to actual workload demand. Five steps: see cost, right-size, tune, automate, monitor.
Databricks cost optimization starts with seeing where spend comes from: mapping cost to the workloads, teams, and clusters that drive it, then right-sizing compute and tuning warehouses from that map. This guide covers the five steps platform teams use — map, right-size, tune, automate, and monitor.
The quarterly cost review lands, and someone asks: "Why did Databricks go up 40%?" The room goes quiet. Not because the team doesn't care — because nobody has a single view that explains which workloads drove the increase.
That's where most Databricks cost optimization conversations start: not with a plan, but with a mystery. And the instinct, understandably, is to start cutting.
The problem is that cutting without visibility usually trades one surprise for another. You right-size a cluster and break a downstream SLA. You shorten a warehouse timeout and slow down the BI team's morning dashboards. You turn off a "dev" resource that turns out to be the only working staging environment.
The first step to optimizing Databricks cost isn't cutting anything. It's seeing what's actually happening.
## What Makes Databricks Cost Hard to See
[Databricks pricing](https://lakesentry.io/blog/databricks-pricing-explained/) runs on [DBUs](https://lakesentry.io/blog/databricks-dbu-explained/), which are abstract units that meter differently across compute types. A job on all-purpose compute burns DBUs at roughly 2–4x the rate of the same job on jobs compute. SQL warehouses have their own rate. Serverless bundles infrastructure into a higher DBU price. The same logical workload can cost $4 or $40 depending on where it runs.
Layer on top of that: most organizations run multiple workspaces, each with its own clusters, jobs, warehouses, and tagging practices. Cost data exists, but it's usually missing the one thing you actually need: who owns the spend, and why it changed.
That's the structural challenge: Databricks isn't expensive in the abstract, but it's complex enough that aggregate numbers don't explain themselves, and the explanation is where the actual optimization lives.
## Start with the Cost Map, Not the Scissors
The teams that reduce Databricks spend reliably have one thing in common: they know what they're spending on before they start changing things. This sounds obvious. In practice, most environments skip straight to tuning without first establishing what's actually driving cost.
A useful cost map answers three questions:
- **By workload type:** How much goes to jobs vs. SQL warehouses vs. interactive clusters vs. streaming? The split matters because the optimization levers are completely different for each.
- **By team or project:** Who is consuming what? Not just "which workspace" but which team, which pipeline, which business domain. Without this, every optimization conversation becomes a negotiation with no data.
- **By time pattern:** When does spend peak? Are there [scheduling collisions](https://lakesentry.io/blog/databricks-spend-changes/)? Is there a steady baseline of "always-on" compute that nobody's watching?
Building this map from system tables is possible but labor-intensive. The bigger challenge isn't the initial build — it's maintaining it as teams reorg, pipelines get renamed, and new workspaces appear. The map has to stay alive, or it becomes another stale dashboard that nobody trusts. Once you have the map, the optimization priorities usually become obvious.
The hardest part of cost optimization is almost always figuring out where to look, not what to do once you're looking.
## Cluster Right-Sizing and Idle Detection
Interactive clusters are where the most avoidable spend hides, because they're designed for convenience, not cost efficiency.
The pattern goes like this: someone spins up a cluster for notebook development. The instance type is generous because the work requires it at peak. The cluster runs all day. Peak usage is maybe 3 hours. The other 5 hours, it's sitting idle, burning DBUs at the interactive rate, which is the most expensive rate Databricks offers.
Multiply that across a platform team of 15 people, each with their own interactive cluster, and you're looking at significant spend that doesn't correspond to any actual compute work. A cluster that runs 168 hours a week with 12 hours of actual task execution has a 7% utilization rate. Most batting averages are higher.
The fix isn't to take clusters away, because interactive compute is legitimately important for development. The fix is structural:
- **Auto-termination defaults.** Every interactive cluster should have an auto-termination timeout. The default of "never" is the most expensive default in Databricks. 30-60 minutes covers most interactive workflows without being annoying.
- **Cluster policies.** Cap instance types and worker counts for interactive use. Developers rarely need 8-node clusters for notebook work. If they do, make it an explicit request with a justification.
- **Separate interactive from production.** Jobs that started as notebooks and got promoted to "scheduled" should move to jobs compute. The DBU rate difference alone is worth the migration effort.
For idle detection at scale, the diagnostic approach is straightforward: compare total cluster uptime against actual task execution time, per cluster, per week. Resources where the ratio is below 20% are candidates for review. (See the [waste detection docs](https://docs.lakesentry.io/concepts/waste-detection/) for how LakeSentry classifies these signals.)
## SQL Warehouse Optimization
SQL warehouse cost is deceptive because it combines three variables that move independently: sizing, scaling behavior, and uptime.
**Sizing.** Warehouses come in T-shirt sizes (2X-Small through 4X-Large), and the cost scaling is roughly linear: a Medium costs ~4x a 2X-Small. Many warehouses are oversized for their actual query load because someone picked a size during setup and never revisited it. The diagnostic: check the warehouse's peak concurrent queries against its capacity. If peak concurrency is 3 and the warehouse can handle 20, it's oversized.
**Serverless vs. classic.** Serverless warehouses eliminate the cold-start problem and infrastructure management overhead. They also cost more per DBU. The tradeoff is simple in theory: serverless wins when utilization is bursty (lots of idle time between queries), classic wins when the warehouse runs consistently. In practice, most teams default to serverless because it's easier — which is fine for development, but worth revisiting for production BI workloads that run on predictable schedules.
**Auto-stop.** This is the single highest-ROI setting in Databricks SQL and the one most often misconfigured. A warehouse with auto-stop set to "never" costs the same whether it's running queries or sitting idle at 3 AM. Setting auto-stop to 10-15 minutes catches most idle periods without affecting users. Serverless warehouses restart in seconds, so there's almost no reason not to set aggressive auto-stop.
## Photon: When It Helps and When It Doesn't
[Photon](https://docs.databricks.com/aws/en/compute/photon) is Databricks' native vectorized engine. It runs supported operations faster, but at a higher DBU rate. The net cost impact depends on whether the speedup outweighs the rate increase.
Where Photon reliably saves money: large scans, heavy aggregations, filter-intensive queries, wide table reads. The wall-clock reduction more than offsets the higher per-DBU cost.
Where Photon doesn't help: Python UDFs (Photon can't accelerate them), small datasets where the speedup is negligible, ML training workloads, and anything dominated by I/O rather than compute. In these cases, you're paying the higher rate without the corresponding speedup.
The mistake most teams make is enabling Photon globally because "faster is better." That's true for the workloads Photon accelerates. For everything else, it's just a more expensive way to do the same work.
The practical approach: enable Photon selectively, starting with your heaviest SQL and ETL workloads. Compare total job cost (not just runtime) before and after. If total cost goes down, keep it. If it doesn't, turn it off for that workload. The honest answer is sometimes "Photon doesn't help here," and that's a useful finding since it removes a variable from your optimization equation.
## Predictive Optimization and Unity Catalog
Databricks' built-in predictive optimization automatically manages table maintenance operations: compaction, OPTIMIZE, VACUUM, file sizing. It's genuinely useful for reducing storage costs and improving read performance on Delta tables that would otherwise accumulate small files over time.
What it doesn't do: optimize compute cost. Predictive optimization works at the table level — it doesn't know which jobs are expensive, which clusters are idle, or which teams are driving cost increases. It's a storage and query performance feature, not a cost management feature.
This is a common source of confusion: teams enable predictive optimization expecting their Databricks bill to drop, then discover that compute is 80%+ of their spend, and compute optimization requires an entirely different set of levers.
Unity Catalog itself contributes to cost management indirectly, by providing a governance layer that makes it possible to track who accesses what. Governance creates the conditions for attribution, but someone (or something) still has to do the attribution work.
## Performance Tuning That Saves Money
Some optimizations reduce runtime and cost simultaneously. These are worth prioritizing because they make workloads faster and cheaper.
**Partition pruning.** A query that scans an entire table because the partition filter doesn't match the physical layout is doing 10-100x more I/O than necessary. The symptom: a query that "should be fast" takes minutes, and the Spark UI shows a full table scan. The fix is usually straightforward — align the query's filter predicates with the table's partition columns. When this works, the cost reduction can be dramatic.
**Shuffle reduction.** Joins and aggregations that produce large shuffles are the most common performance bottleneck in Spark. A poorly planned join can turn a 5-minute job into a 45-minute job. The 40 extra minutes are pure cost. Look at the Spark UI's stage breakdown: stages with large shuffle writes and long task durations are the candidates.
**Caching strategy.** Disk caching and Delta caching reduce repeated reads from cloud storage. For workloads that re-read the same data (iterative ML, BI dashboards hitting the same tables), caching can cut I/O cost significantly. For single-pass ETL, caching adds overhead without benefit.
**Runtime version.** Clusters pinned to old Databricks runtimes miss engine improvements — better Adaptive Query Execution, improved Delta read paths, smarter shuffle handling. The workload keeps running, which is why nobody updates the runtime, but it runs slower than it would on a current version. Checking whether your heaviest workloads run on a current LTS runtime is a small effort with occasionally large payoff.
For a detailed walkthrough of the seven most common cost drivers and how to diagnose each one, see [7 reasons Databricks spend changes](https://lakesentry.io/blog/databricks-spend-changes/).
## Automation: From Visibility to Action
After going through the manual optimization cycle a few times, most teams start asking: "Can we automate this?"
The answer is yes, but the sequence matters.
Automation works when it follows a trust ladder:
1. **See.** Automated monitoring surfaces cost changes and their drivers. No action — just visibility, delivered consistently.
2. **Understand.** Each flagged change comes with context: which workload, which owner, whether it's expected. The team reviews and builds confidence in the signal quality.
3. **Decide.** The tool proposes a change — stop an idle warehouse, right-size a cluster, clean up an orphaned resource — with the evidence behind it. A human reviews it, approves it, and makes the change, with an audit trail of what was decided and why.
4. **Codify.** Only the changes the team has already made by hand often enough to trust: a cluster policy, an auto-stop default, a scheduled cleanup job. Bounded, reversible, with a kill switch.
The trap is when teams are jumping straight to step 4. Automation without explainability is a faster way to break things. A script that terminates "idle" clusters without knowing that one of them is a long-running streaming job is worse than no automation at all.
The principle is simple: automation shouldn't outrun your understanding of what it's automating. Start with consistent visibility. Let the decisions you'd make manually become obvious enough to codify them with guardrails.
Optimization that lasts follows a progression — map first, automate last.
## An Optimization Workflow That Lasts
One-off optimization projects produce one-off results. The environment changes and costs drift back up. The pattern that actually works is a recurring weekly loop:
1. **Weekly review** of the top cost movers, e.g. top 10.
2. **Ownership assignment.** Every top mover gets an owner who can say "expected" or "needs investigation."
3. **One change at a time.** Treat cost changes like production changes. Small steps, measured impact, rollback path. The goal is to make steady, safe progress.
4. **Document and learn.** Track what you changed, why, and what happened. Over time, this becomes a playbook that makes the next optimization faster.
The teams that sustain cost optimization are the ones with a consistent process — a weekly loop that catches drift before it compounds, and an ownership model that turns "someone should look at this" into "this particular person will look at it by Thursday."
---
The most impactful Databricks cost optimization is having a normalized view of what's happening across every workspace so the decisions about what to change become obvious before anyone has to guess. LakeSentry allows you to have a comprehensive view of your entire Databricks estate.
If you're weighing tools for this, see the [Databricks cost tools comparison](https://lakesentry.io/compare/databricks-cost-tools).
---
## DBUs Explained: What They Are, How They Cost, How to Optimize
- URL: https://lakesentry.io/blog/databricks-dbu-explained/
- Published: 2026-05-04
- Updated: 2026-07-28
- Author: LakeSentry Team
- Category: compute-fundamentals
- Tags: databricks, dbu, pricing, cost-optimization, finops
> A DBU is the metering unit Databricks uses to bill compute, with rates that differ by compute type. How to tune DBU spend without risking workloads.
If you've ever looked at a Databricks bill and thought "okay... but what is a DBU, and why is my bill the way it is?", you're not alone. DBUs are the unit behind most of Databricks' pricing, but they're abstract enough that it's hard to connect them to specific workloads.
This post is a practical walkthrough: what a DBU is, how DBU cost gets calculated, what drives consumption across common workload patterns, how to troubleshoot a spend change when it happens, and a few [optimization moves](https://lakesentry.io/blog/databricks-cost-optimization/) that don't put your environment at risk.
## What Is a DBU?
A DBU is the unit Databricks uses to meter compute consumption, normalized so [pricing](https://www.databricks.com/product/pricing) stays consistent across different workload types and configurations. It's closer to "how much of this Databricks compute category did you consume" than to "CPU hours" or "compute time."
Two practical implications:
1. **DBUs tell you "how much" of a category you used, not "why."** You still need workload context to explain the driver behind a number.
2. **DBU rates can differ by compute type and plan.** Jobs/batch, SQL warehouses, all-purpose clusters, and serverless can be priced differently depending on your Databricks setup and your cloud provider terms.
DBUs are the cost units, but you still need a method to map them back to the work that produced them.
## How DBU Cost Is Calculated
At a high level, the DBU portion of your Databricks bill is calculated as:
**DBU Rate x DBUs Consumed = DBU Cost**
That's only part of the total, though: the underlying cloud infrastructure (VMs, storage, networking) is billed separately by your cloud provider and sits on top of the DBU cost.
To estimate spend or audit a usage spike, you typically need:
- **Consumption:** total DBUs used over a specific period (day/week/month).
- **SKU rate:** the specific price per DBU for your workload. Rates vary significantly between Jobs, SQL, and All-Purpose compute.
- **Attribution:** a breakdown by cluster, job, or team to identify which resources are driving the spend.
If you don't have a DBU number yet, our [Databricks cost calculator](https://lakesentry.io/databricks-cost-calculator/) works the other way round: you describe the workloads you run, and it derives the hours, DBUs, and monthly cost.
The DBU billing formula — same cluster, different SKU = different bill.
## Common Workload Types
DBUs show up across many categories of Databricks usage, but consumption patterns can look different depending on what you're running.
At a high level:
- **Jobs / batch workloads**: DBUs are driven by how long jobs run and how much parallelism you use at peak.
- **SQL / warehouses**: DBUs are driven by query volume, concurrency, and "always-on vs on-demand" patterns.
- **ML / experimentation**: DBUs can be spiky and developer-driven (ad-hoc work, iterative training runs, environment churn).
- **All-purpose / interactive clusters**: DBUs are often sensitive to "left running" time and concurrency.
Exact category mappings and rate differences depend on your Databricks plan and configuration.
Each compute type burns DBUs at a different multiplier. The same work can cost 2x more depending on SKU.
## What Drives DBU Consumption
Most "why did our DBU spend change?" investigations come back to the same handful of levers. Knowing the categories ahead of time makes the diagnosis faster when something moves.
### Runtime and concurrency
The most common driver, and usually the first place to look. Workloads run longer than they used to, more workloads run at the same time, or a backfill extends past the window it was scoped to. None of these change the *shape* of what the platform is doing — they change how much of it is happening, and when.
### Cluster sizing and resource selection
Spend can move even when runtime is steady. A driver gets bumped up for a one-off and stays bumped. Autoscaling bounds get widened during an incident and never get tightened again. A workload migrates from jobs compute to all-purpose compute because it was easier to develop that way, and the rate difference quietly compounds across every run.
### Workload efficiency
This is the invisible multiplier. A retry loop kicked off by an upstream schema change. Data skew that turns a fast stage into a long tail. A query pattern that scans far more data than it needs to because a filter stopped pruning correctly. Small code changes that double the shuffle or I/O cost without anyone realizing. The total work goes up; the business output doesn't.
### "Always-on" vs "on-demand"
Often the answer isn't "more work" but "the same work, on resources that never turn off." Warehouses running past their peak window, clusters idling between jobs, dev and test resources that drift into production-like uptime because nobody's watching them. The DBU rate while idle is the same as the DBU rate while busy.
### Environment hygiene
The slow creep. Orphaned clusters from projects that wrapped months ago. Warehouses spun up for a launch and never decommissioned. Whole environments left running long after the work moved on — from one-off POCs, dev environments, etc. Nobody meant to do any of this, which is exactly why it accumulates: there's no single moment where someone decides to keep paying for it.
## A Practical Workflow for When Spend Changes
If you want "DBU calculator" accuracy, you eventually need the right rates. But to manage spend, you need explainability first.
Here's a simple troubleshooting workflow that works in most environments:
1. **Baseline your top DBU consumers by workload**
- Identify the top drivers (jobs, warehouses, clusters, teams/projects, environments)
- Start with "top 10," not "everything"
2. **Track deltas (daily/weekly) to catch what changed**
- Don't stare at totals; track "what moved since last period?"
- Look for the first day the curve changed direction
3. **Assign ownership for the top drivers**
- "Shared" is a cost category, but it can't be an ownership model
- Make sure every major driver has someone who can confirm expected vs unexpected
- (For how LakeSentry models this with attribution rules and chargeback, see the [cost allocation docs](https://docs.lakesentry.io/features/cost-allocation/).)
4. **Test safe optimizations and verify impact**
- Treat changes like production changes: small steps, measure, rollback path
- Confirm the DBU impact *and* the performance/reliability impact
This is where many teams discover the difference between [native Databricks cost tools](https://lakesentry.io/blog/native-databricks-cost-tools/) (visibility, exports, tables) and what a [cost transparency](https://lakesentry.io/blog/databricks-finops-101/) layer adds (driver breakdown, attribution, and workflow). For a diagnostic checklist of the most common spend drivers, see [7 reasons Databricks spend changes](https://lakesentry.io/blog/databricks-spend-changes/).
## FAQ
**1. What does DBU stand for?**
DBU stands for Databricks Unit, the normalized unit Databricks meters to bill compute, charged per second of use. It measures processing capability consumed, not a fixed amount of CPU or memory.
**2. What is a DBU in Databricks?**
A DBU is the metering unit behind most Databricks pricing. The DBUs a workload consumes depend on its compute type, instance size, and runtime, and the dollar rate per DBU depends on the compute type, tier, cloud, and region.
**3. How do you convert DBUs to dollars?**
Multiply DBUs consumed by the per-DBU rate for that workload's SKU, then add the cloud infrastructure billed separately for classic compute. There's no single DBU-to-dollar rate; it varies by compute type, tier, cloud, and region. See [Databricks pricing explained](https://lakesentry.io/blog/databricks-pricing-explained/) for the rate card.
**4. Do all compute types use DBUs at the same rate?**
No. Jobs compute, all-purpose compute, SQL warehouses, and serverless each meter DBUs at different rates. The same workload can cost several times more on all-purpose than on jobs compute.
## Using a Cost Transparency Layer
You can get a long way with built-in Databricks cost monitoring tools such as native exports, system tables, and dashboards — especially for baseline visibility. Where most teams stall is the operational layer above that: attribution that holds up across reorgs and renamed pipelines, explainability when a number moves, and a workflow the team runs when it does.
That's the layer LakeSentry is built for. It produces a continuously updated breakdown of DBU cost drivers by workspace, job, and cluster, with ownership derived from your existing tags and team mappings, so the conversation can move from "we see the DBUs" to "we know what changed and who should look at it."
---
## 7 Reasons Databricks Spend Changes (and How to Diagnose Each One)
- URL: https://lakesentry.io/blog/databricks-spend-changes/
- Published: 2026-05-02
- Author: LakeSentry Team
- Category: cost-optimization
- Tags: databricks, cost-optimization, dbu, cost-allocation, diagnostics
> When Databricks spend moves, start here. Seven common drivers from DBU multipliers to retry storms, with diagnostic steps and safe first moves for each.
When Databricks spend moves, the main question is what actually changed: which workload, which config, which schedule. In this post, we have summarized seven common spend change drivers we see again and again, how to confirm each one, and a safe first step you can take without turning Databricks cost optimization into a firefight.
## Before You Start: Separate DBUs from Cloud Costs
Your Databricks bill is really two layers stacked on top of each other. The DBU Databricks cost is what Databricks meters for its own usage. The cloud-infra layer is what your cloud provider charges separately for the underlying VMs, storage, and network (except in the [serverless](https://docs.databricks.com/aws/en/compute/serverless) case, where Databricks runs the infrastructure in their account and bundles it into a higher DBU rate).
Most of the time the two layers move together, because the VMs running the workloads are also the thing producing the DBUs. But the ratio between them can shift in ways that change which lever actually matters:
- A storage-heavy workload pushes the cloud bill up faster than DBUs.
- A migration from classic compute to serverless can show up as "higher DBUs, lower cloud-infra bill" even when the total cost barely moved.
- An I/O-heavy or egress-heavy job can lift the cloud line without touching DBUs much at all.
The practical implication is that "spend went up" isn't actually one question. Before diagnosing further, it's worth asking: did the DBU line move, did the cloud-infra line move, or both? The drivers below are mostly DBU-side, but several of them show up on both layers, and the fix depends on which one is actually moving.
Once you know the layer, you can attach cost allocation to it: who owns the spend, by team, project, or environment. That's what makes the next step safe.
Seven common spend drivers — each with different symptoms and different safe first moves.
## 1. DBU Multipliers: Same Work, Different DBU Burn
The first thing to rule out is whether the workload itself changed at all, or whether it just moved onto compute that meters differently. DBUs aren't a direct proxy for CPU hours — the same pipeline can consume DBUs at very different rates depending on which compute SKU it's running on. As a rough rule of thumb:
- All-purpose compute runs at roughly 2–4x the rate of jobs compute for the same instance type.
- SQL warehouses are priced on their own SKU.
- Serverless options sit on another rate again, with infrastructure bundled in.
Exact multipliers depend on plan, region, and cloud provider (see [Databricks pricing explained](https://lakesentry.io/blog/databricks-pricing-explained/) for the full rate card).
The symptom is usually a step change rather than a gradual ramp: spend rises in one workload category around a specific date, even though volume looks about the same. That timing is the clue. Compare DBU consumption for the same logical workload before and after the suspected change, and check whether it migrated between SKUs. Migrations between any two of these can produce a sharp shift in consumption with no change in the underlying work.
The safest first move is to standardize compute patterns for that workload class, rather than re-tuning the workload itself. If a category change is genuinely needed, capture before-and-after consumption and runtime so the tradeoff is defensible later.
## 2. All-Purpose Clusters Becoming the Default
All-purpose compute is built for interactive work and it's priced accordingly. The problem starts when it becomes the default layer for production-like workloads, or when shared all-purpose clusters get treated as long-lived infrastructure because nobody owns them enough to take them down.
The symptom looks like background spend: DBUs accumulating outside scheduled job windows, attached to clusters that have long uptime and inconsistent activity. The diagnostic question is whether production jobs or shared pipelines are running there because someone found it convenient, and whether anyone can name an owner. If the best answer to "who owns this cluster?" is "it's shared," that ambiguity is already part of the problem.
Hence, the first step should be to add structure around the usage of all-purpose clusters:
- Separate interactive development from scheduled production with different cluster policies.
- Apply timeouts and auto-termination as guardrails rather than hard blocks.
- Require every long-lived interactive cluster to have an owner and a stated purpose.
If an all-purpose cluster has neither owner nor purpose, then it becomes just additional spend rather than free convenience.
> If the best answer to "who owns this cluster?" is "it's shared," that ambiguity is already part of the problem.
## 3. Failed Jobs and Retry Storms
Retries are one of the highest-leverage drivers on this list, because their cost compounds in ways that don't show up cleanly on a spend chart. A job that fails three times before succeeding doesn't just cost three times the original cost — it re-pays cluster startup each time, often runs longer than the original because it's hitting the same upstream problem from a worse position, and pushes its runtime past its window, which oversubscribes pools and lifts the platform's peak DBU rate. The result is a lump on the spend chart that looks like "more usage" when it's really "the same work, run twice, on a hotter fleet."
The diagnostic question is whether the top movers correspond to jobs with elevated failure rates or long retry chains, and whether those failures correlate with something upstream:
- A recent schema change that broke a downstream cast.
- A flaky dependency or external API timing out.
- A data quality issue surfacing as a null pointer deep in a transformation.
- A memory limit that's been on the edge for weeks and finally tipped over.
Pipelines that are "green eventually" but expensive along the way are the ones to look at first.
> Pipelines that are "green eventually" but expensive along the way are the ones to look at first.
## 4. SQL Warehouses Scaling Up — or Never Scaling Down
SQL spend is often the hardest to read because warehouse sizing, autoscaling, and uptime all move together with traffic. A small change in usage pattern can produce a large change in DBU burn if the warehouse is scaling up frequently or staying on through long idle periods.
The symptom is SQL spend drifting in a way that doesn't quite match query volume. The clue usually shows up by comparing scaling events, peak concurrency windows, and idle vs active time. If a warehouse is effectively always-on — that's worth checking before assuming users are just running more queries.
The core approach to mitigation is tuning for on-demand by design: sensible auto-stop windows, scaling boundaries that match actual concurrency.
## 5. Scheduling Collisions
Most environments don't have a concurrency strategy — schedules evolved organically, jobs got copied with their cron strings intact, and two unrelated heavy workloads ended up starting at the top of the same hour because someone borrowed a config three years ago. Overlaps push the platform into higher peak capacity (more clusters, more autoscaling, more warehouse expansion), which lifts DBUs even when the total amount of work hasn't changed.
The fastest way to spot this is to map the top DBU consumers to a timeline. Pile-ups are usually obvious once you see them:
- Multiple big jobs sharing a start minute.
- Backfills running into BI peak windows.
- CI-triggered jobs colliding with scheduled batch runs.
- Streaming jobs each sized for their own worst case running concurrently.
The first move is small: shift one non-critical heavy workload off-peak and watch the runtime and downstream impact for a week before deciding on the next one. The mistake to avoid is staggering jobs without understanding the dependency graph.
> The mistake to avoid is staggering jobs without understanding the dependency graph.
## 6. Environment Sprawl
The slowest, most reliable driver on this list is dev/test environments quietly accumulating long-lived resources, generous defaults, and CI workloads that nobody monitors in aggregate. There's rarely a single "big change", but rather a slow additional cost growth every month.
Two patterns show up especially often. The first is development modes that keep clusters up for long working windows, which is great for productivity and expensive when nobody's watching. The second is CI-driven workloads triggered on every commit, which are great for velocity until someone notices the aggregate.
To diagnose, break spend down by environment — using whatever your org uses for separation, whether that's tags, workspaces, or service principals. A lot of teams already use separate workspaces or service principals per environment, which gives you a natural cost-allocation boundary even before tagging is fully consistent. Look at the largest non-prod movers, and check ownership on each — resources with unclear ownership are usually the ones that never get cleaned up, because there's no single moment when someone decides to keep paying for them.
The fix is operational rather than technical:
- Lifecycle policies for non-prod (auto-stop defaults, cleanup for orphaned resources).
- Cost visibility broken down by owner, so "shared dev" doesn't quietly become "nobody owns it."
- Explicit use of workspace or service-principal boundaries for cost reporting and governance, if your org separates environments that way — it's already doing half the work.
## 7. Photon and Runtime Version Drift
The last category is the one that's easiest to miss, because it doesn't look like a change at all — when the workloads, the schedules, and the cluster configs are all the same, but the actual execution engine underneath them changes.
Photon is the obvious example. It's priced at a higher DBU rate than non-Photon compute, but it can execute supported operations significantly faster, which means total spend can go either way depending on the workload. Teams often flip Photon on globally because "faster is better," and end up paying the higher rate on workloads that don't really benefit:
- UDF-heavy code where Photon can't accelerate the hot path.
- Small jobs where the speedup doesn't outpace the rate multiplier.
- Queries dominated by operations Photon doesn't support.
The reverse also happens: a workload that *would* benefit from Photon stays off it because nobody re-evaluated the default after it was set two years ago.
Runtime version drift is the quieter cousin of the same problem. Clusters pinned to older Databricks runtimes miss the optimizations and engine improvements that ship with newer LTS releases — better Adaptive Query Execution, improved Delta read paths, smarter shuffle behavior. The cluster keeps working exactly as it did, which is why nobody touches it, and the workload quietly runs slower (and burns more DBUs) than the same job would on a current runtime.
The diagnostic question is whether the engine settings still match the workload. For Photon, that means looking at whether it's enabled on workloads that actually benefit, and disabled on the ones it just makes more expensive — Spark UI's stage breakdown is usually enough to tell. For runtime versions, it means checking how old the pinned runtimes are across the platform, and whether the oldest ones are running the heaviest workloads.
The first step is small and reversible: pick one heavy workload, test it on the alternative configuration (Photon on/off, or current LTS runtime vs the pinned one), and compare runtime and DBU consumption. The answer is sometimes "the current setup is fine," and that's still a useful result, because it removes a suspect from the list.
> The answer is sometimes "the current setup is fine," and that's still a useful result, because it removes a suspect from the list.
## A Weekly Review Loop
For teams trying to reduce Databricks cost reliably, the fastest win usually is to establish a short weekly loop — which makes the difference between guessing and running controlled engineering changes:
1. Baseline the top drivers by workload.
2. Track week-over-week deltas, not just totals.
3. Assign ownership for the top movers — including "expected, no action" as a valid outcome.
4. Make one safe change at a time, with a rollback path.
For more on the underlying mechanics — how DBUs are metered, where they come from, and how the bill actually adds up — see our [DBU explainer](https://lakesentry.io/blog/databricks-dbu-explained/).
## Native Tools vs a Transparency Layer
Native exports, system tables, and dashboards are the right starting point — they give you the raw material. The hard part is turning "we see the number" into "we know what changed, who owns it, and what we can safely do next" without rebuilding that work every quarter in a spreadsheet someone forgets to maintain.
That's what LakeSentry is built for: a continuously updated breakdown of cost drivers by workspace, job, and cluster, with cost allocation derived from your existing tags and team mappings. So an investigation starts with a shortlist instead of a hunt. For how the platform flags meaningful changes early, see the [anomaly detection docs](https://docs.lakesentry.io/concepts/anomaly-detection/). For more on what native tools can and can't do here, see [why native cost tools are not enough](https://lakesentry.io/blog/native-databricks-cost-tools/).
---
## What Native Databricks Cost Tools Show — and What They Don't
- URL: https://lakesentry.io/blog/native-databricks-cost-tools/
- Published: 2026-04-30
- Author: tatiana-zimovets
- Category: cost-optimization
- Tags: databricks, cost-transparency, native-tools, cost-attribution
> Native Databricks cost tools show totals from billing exports, system tables, and dashboards. They don't say what changed, who owns it, or what to do.
When Databricks spend changes, the question that matters is: what changed, and why?
Most teams already have "native" visibility: billing exports, system tables, usage dashboards, cluster/job metrics, maybe some tagging. That gets you the totals. But getting from "spend went up" to "this workload changed because of this reason, and this person can fix it" requires connecting cost signals to owners and drivers — not just charts.
## What Teams Mean by "Native Databricks Cost Tools"
In practice, "native" refers to a mix of:
- Billing and usage exports (to cloud storage / your warehouse)
- [System tables](https://docs.databricks.com/aws/en/admin/system-tables) (`system.billing.usage`, `system.compute.clusters`) and queryable usage data
- Built-in UI dashboards or notebooks that summarize usage
- Cluster and job metrics (who ran what, when)
- Tagging / metadata (when it's used consistently)
These are real signals. The gaps show up when you try to answer questions that have to be answered *operationally*, not academically.
## What Native Tools Are Good For (and You Should Use Them)
Native tooling is a strong foundation for:
- **Baseline visibility:** total spend trends, big movers over time, top workspaces or clusters by usage
- **Early anomaly detection (coarse):** "something changed yesterday" at the account/workspace level
- **Source-of-truth raw signals:** exports and system tables you can model and enrich
- **Shared language:** a common place to start the conversation when [FinOps](https://lakesentry.io/blog/databricks-finops-101/) and platform teams review spend
Native tools answer "what's the total?" well. The question they struggle with is "what changed and who owns it?"
## The Real Blocker: Databricks Cost Model Complexity
Databricks costs rarely map cleanly to a single dimension.
Even with a clean export, spend can be driven by a combination of:
- Workloads that change shape (batch vs streaming, backfills, retries)
- Shared compute patterns (shared clusters, shared jobs, shared orchestration)
- Environment differences (dev/stage/prod) that blur together when ownership isn't enforced consistently
- Product and platform features that create indirect cost
That's why aggregate charts often produce the same frustrating outcome:
> You can see that spend changed. You can't say *why* it changed.
The complexity is real, and native tools surface it faithfully. What they don't do is resolve it — connect the cost line to a workload, an owner, and an explanation. For a diagnostic checklist of the most common drivers, see [7 reasons Databricks spend changes](https://lakesentry.io/blog/databricks-spend-changes/).
## Visibility vs Explainability: "What Changed?" Is the Question That Matters
A dashboard that shows "compute went up 18%" tells you something happened. It doesn't tell you what to do about it.
Explainability means you can reliably answer:
- Which workload drove the increase?
- Which team, project, or environment owns it?
- Was the driver more data, more runtime, a config change, or retries?
- Is this a one-off event or a trend that will repeat tomorrow?
Native signals help, but they don't automatically produce a driver narrative. That requires attribution logic (mapping cost to owners) and workflow discipline (acting on what you find).
Native tools cover visibility. Explainability — the part that drives action — requires a different layer.
## Ownership and Attribution Break Down in the Real World
Attribution fails for boring reasons:
- Tags exist, but they're missing or inconsistent
- Naming conventions drift over time
- Resources are shared across teams, and "shared" becomes synonymous with "nobody owns it"
- The mapping from technical identifiers (job/cluster/workspace) to business ownership (team/project/env) isn't maintained
When this happens, you end up with visibility without accountability. You can point to the cost, but not to an owner who can validate whether it's expected — and fix it if it's not.
Cost transparency requires an enforced ownership model. For how LakeSentry models attribution and confidence tiers, see the [cost attribution docs](https://docs.lakesentry.io/concepts/cost-attribution/).
## Operationalization Is the Hard Part (Not Charts)
Even when teams can compute attribution, the bigger challenge is making it repeatable:
- Who reviews deltas, and how often?
- What threshold triggers investigation?
- Where do explanations get captured so you're not re-learning the same lesson next month?
- How do you turn "this job got expensive" into a remediation task that ships?
Without a workflow, cost work becomes a series of urgent deep-dives that never create a lasting system. The loop that works is short: signal → owner → explanation → action. For a deeper look at how DBU costs drive these signals, see the [DBU explainer](https://lakesentry.io/blog/databricks-dbu-explained/).
## What "Cost Transparency" Looks Like in Practice (a Checklist)
If you're evaluating whether your current setup is "enough," here's a practical definition.
You have cost transparency when you can deliver:
- **Consistent ownership** (team/project/env) across your Databricks spend
- **Reliable attribution logic** that survives new workloads, new clusters, and platform evolution
- **Explainability**: deltas come with drivers, not just totals
- **Visibility where it matters**: investigations shouldn't take days
- **Workflow integration**: an operational loop for review, assignment, and remediation
- **Auditability**: you can show how a number was computed and why it changed
Native tooling contributes to several of these, but closing the full loop usually requires dedicated investment — either internal tooling or a platform built for it.
## How to Build Toward Cost Transparency (Pragmatic Steps)
If you're starting from "we have exports and dashboards," these steps are a practical path forward:
1. **Define ownership first (before you build dashboards)**
- Decide what "owner" means (team, cost center, platform domain, product line)
- Define how it's represented (tags, policies, mapping tables)
- Make it enforceable, not aspirational
2. **Standardize attribution inputs**
- Enforce tagging rules where you can
- Create a mapping layer for the places you can't (shared services, platform overhead)
- Treat attribution like a product: version it, test it, review changes
3. **Shift from totals to delta reviews**
- Build a weekly (or daily, for fast-moving environments) delta workflow
- Focus on "what changed since last period" instead of "what is the total"
4. **Make investigations faster than the next surprise**
- Capture common drivers and remediation patterns
- Track "known expected changes" (new pipeline launch, backfill window, seasonal load)
5. **Integrate cost monitoring into the way teams already work**
- Route cost deltas to the right owners
- Create a place to document explanations and follow-ups
- Close the loop so you don't re-triage the same pattern repeatedly
## Where LakeSentry Fits
LakeSentry sits on top of native Databricks signals — `system.billing.usage`, billing exports, cluster metadata — and adds the layer most teams can't maintain by hand: attribution that holds up when teams reorg, explainability when a number moves, and a workflow that turns cost signals into owned action items.
For a side-by-side of native tooling and a third-party option, see [native Databricks cost tools vs LakeSentry](https://lakesentry.io/compare/databricks-native-cost-tools) or the full [Databricks cost tools comparison](https://lakesentry.io/compare/databricks-cost-tools).
---
## Why We Built LakeSentry
- URL: https://lakesentry.io/blog/why-we-built-lakesentry/
- Published: 2026-04-28
- Author: konstantin-polukhin
- Category: product
- Tags: lakesentry, databricks, cost-transparency
> We built LakeSentry to give Databricks teams transparency into cost, usage, and adoption — so they understand what's happening and can act safely.
If you've run Databricks for any length of time, you've probably been in this conversation: the bill goes up, a finance partner asks about it in a review, and before anyone can talk about bringing costs down, the team gets stuck on a more basic question: what actually changed, and why?
Most teams can get to visibility. They can pull usage exports, query system tables, and build dashboards that show totals by day, SKU, workspace, or cluster. That part is genuinely solved. The harder part is what comes next: when the number moves, the dashboard confirms that something shifted, but it doesn't say which workload drove the delta, who owns it, or whether it was expected — a backfill, a new pipeline, a traffic spike? And it certainly doesn't suggest what the safest next action is.
That's the gap we kept running into with our clients, on project after project. Smart teams, good tooling, and still days lost to investigations that should have taken minutes — usually because the people who could explain the change weren't the same people watching the dashboard, and the people watching the dashboard didn't have enough context to act. The pattern was always some version of visibility without explainability, and it produced the same downstream effects every time: slow conversations, fuzzy ownership, and remediations risky enough that nobody really wanted to be the one to approve them.
> … the people who could explain the change weren't the same people watching the dashboard, and the people watching the dashboard didn't have enough context to act.
## The Pattern
Early on, a Databricks setup is easy. A few teams, a handful of pipelines, workloads you recognise on sight. Then adoption catches up: more teams, more jobs, streaming, warehouses for new use cases, separate environments — and the cost picture starts behaving in ways a monthly total can't really explain.
The examples are familiar once you've seen a few. A [retry loop kicks off after an upstream schema change](https://lakesentry.io/blog/databricks-spend-changes/) and doubles compute for hours before anyone notices. A warehouse stays on after a traffic peak because nothing turned it back down. Clusters spun up for a project keep running long after the project wrapped. A backfill gets waved through as "expected," except the window was supposed to close yesterday.
None of this means someone wasn't paying attention — it's just what happens on a platform doing real work for a lot of people at once.
Spotting the shift isn't the hard part; most teams see it by the next morning. The hard part is the story behind it — which workload moved, why, whether it'll keep moving, and what's safe to do about it. Without that story, the investigation drags, ownership gets fuzzy, and the fix turns into something nobody really wants to approve.
> Then adoption catches up: more teams, more jobs, streaming, warehouses for new use cases, separate environments — and the cost picture starts behaving in ways a monthly total can't really explain.
## Scaling Your Cost Understanding
Databricks is built to scale — more workloads, more teams, more data, more velocity. That's the point of it, and it's one of the main reasons why people pick it.
Cost understanding tends to scale more slowly, because it depends on things that don't show up automatically with adoption: someone who clearly owns a given workload or warehouse, an attribution model that holds up when teams reorg or pipelines get renamed, and a workflow the org actually uses to review changes and decide what to do about them. When any of those are missing, spend just becomes background noise until something spikes hard enough to force a conversation.
And that conversation usually plays out the same way. A platform owner opens the dashboards and exports. People spend a while debating whether the number is even real or a billing mistake. Someone asks who owns the workload, and the answer is some version of "kind of us, kind of them." The team burns a day or two hunting for a plausible explanation, and by the time someone proposes a fix, everyone hesitates — because the blast radius isn't clear and nobody wants to be the one who broke production trying to save DBUs.
The longer that loop takes, the more it costs — and not just in dollars. It also costs attention, which is the scarcer resource on most platform teams.
## Explainability is the Point
Databricks provides some quite robust [cost monitoring capabilities out of the box](https://lakesentry.io/blog/native-databricks-cost-tools/). The exports, system tables, and dashboards Databricks gives you are genuinely useful, and any team running the platform seriously ends up leaning on them.
The problem is that most of the operational pain doesn't come from the question "what's the total?". It comes from the next question: what changed, and why? And answering that one means connecting three things quickly: the driver, the context around it, and the owner — the person who can say whether this was expected and decide what to do next.
That's really what we mean by **Databricks cost transparency**: enough of an explanation that the team can act on it, before a delta turns into an incident.
> The problem is that most of the operational pain doesn't come from the question "what's the total?". It comes from the next question: what changed, and why?
## Automation Should Always Come with Control
In practice, automation tends to work best when it follows a progression rather than landing all at once. The first step is read-only discovery — surfacing the drivers quickly and consistently, without anything moving yet.
The second is approval with a real audit trail: when a remediation gets suggested (stop something idle, right-size a warehouse, clean up a cluster nobody's claimed in weeks), the team should be able to see why it was suggested, approve it explicitly, and look back later at who approved what and on what basis. Only once that loop is genuinely trusted does it make sense to let some of those actions run on their own. And even then, it should be opt-in, bounded, and reversible.
That last word matters more than people tend to expect. Control isn't the opposite of speed; it's the thing that makes speed safe to use. The principle we ended up building LakeSentry around is a simple one: automation shouldn't outrun explainability.
> Control isn't the opposite of speed; it's the thing that makes speed safe to use.
## What We Built LakeSentry to Do
Everything in LakeSentry is oriented around shortening the time from "spend changed" to "we understand why, and we know what to do next."
In practical terms, that means helping teams:
- Find the main cost drivers quickly (in a way that matches how the org thinks: by workload, owner, environment)
- Preserve ownership so "shared" doesn't turn into "nobody"
- Detect meaningful changes early, with evidence attached
- Take action with guardrails (read-only → approve → opt-in automation)
For a deeper walkthrough of the architecture and how each piece fits together, see [how LakeSentry works](https://docs.lakesentry.io/concepts/how-lakesentry-works/) in the docs.
LakeSentry Cost Overview — cost drivers, trends, and potential savings in one view.
## The "Visibility → Explainability → Safe Action" Ladder
We didn't want to start with the Databricks cost optimization pitch because the teams we work with aren't short on reasons to optimize, they're short on the confidence to act: what's really driving the spend, who owns it, and whether the fix is safe.
So we built LakeSentry in that order. **Explain first, then make the action safe, then make the loop repeatable.** Optimization follows from that.
If you're evaluating your own setup, here's a simple framework:
1. **Visibility:** you can see totals and trends
2. **Explainability:** you can attribute a change to a driver + owner, quickly
3. **Safe action:** you can remediate with guardrails and auditability
The cost transparency ladder — most teams have step 1, but pain lives in steps 2 and 3.
Most teams have step 1, but pain lives in steps 2 and 3.
LakeSentry is built for those steps — because they're the ones that turn cost data into operational clarity.
## The Next Step
If you're evaluating cost transparency for Databricks and want to talk through what "enough" looks like for your environment, you can always reach out to us, and we would be happy to discuss your case.
---
# Comparisons (full text)
Full text of LakeSentry's Databricks cost tool comparison pages.
## Databricks Cost Optimization Tools Compared
- URL: https://lakesentry.io/compare/databricks-cost-tools/
- Published: 2026-06-01
- Updated: 2026-08-05
- Category: comparison
- Tags: databricks, cost-tools, comparison, alternatives
> Compare Databricks cost tools — native tooling, LakeSentry, Unravel, PointFive, Espresso AI, LakeSight, and Zipher — by scope, pricing, and automation.
Databricks cost optimization tools fall into four groups: native Databricks tooling, cost intelligence platforms, autonomous optimization engines, and broad efficiency or FinOps platforms. This page compares the main options by scope, pricing, and automation model, based on each product's public materials as of May 2026. LakeSentry is one of them, and the comparison covers it on the same terms as the rest. For how Databricks itself prices compute (DBUs, tiers, and clouds), see [Databricks pricing explained](https://lakesentry.io/blog/databricks-pricing-explained/).
## The four categories
1. **Native Databricks tools** — free and built in: system tables, importable cost dashboards, budgets, cluster policies, tags. They report usage and leave analysis and action to you.
2. **Cost intelligence platforms** (LakeSentry, LakeSight) — sit on top of system tables and turn raw usage into attribution, monitoring, and, for LakeSentry, anomaly detection and guided plans.
3. **Autonomous optimization engines** (Espresso AI, the repositioned Zipher) — focus on cutting compute cost automatically, with the result showing up as a lower bill.
4. **Broad efficiency and FinOps platforms** (Unravel, PointFive, Finout) — cover Databricks as one part of a wider estate spanning other data platforms or the whole cloud.
## The tools
### Native Databricks tools
System tables such as `system.billing.usage` are the authoritative usage record, paired with importable cost dashboards, budgets, and cluster policies. They are free and accurate. The gaps are cross-workspace consolidation, automatic attribution, cost anomaly detection, and any optimization workflow — all of which you build yourself on top.
> **Fits:** single-workspace teams with engineering time to spend on cost SQL.
See the [native cost tools comparison](https://lakesentry.io/compare/databricks-native-cost-tools) and the deep dive on [native Databricks cost tools](https://lakesentry.io/blog/native-databricks-cost-tools/).
### LakeSentry
A Databricks-only cost intelligence platform. It connects read-only through a service principal, normalizes the cost ledger across workspaces, attributes spend by job and team, detects anomalies with statistical evidence, and turns each finding into a guided plan your team applies in Databricks. It stays read-only and never requests write permissions. Pricing is public and flat per user: $0 Free, $499 Standard, $849 Pro per month, billed annually, with unlimited workspaces on every tier.
> **Fits:** Databricks-focused teams that want attribution and anomaly detection plus a ranked plan of what to change, with predictable pricing.
### Unravel Data
A multi-platform data observability product covering Databricks, Snowflake, BigQuery, EMR, and Cloudera. It pairs cost analytics with performance tuning such as code rewriting and autoscaling fixes, and positions as an autonomous operator. Pricing is consumption-based and quoted through a demo.
> **Fits:** organizations running several data platforms that want one performance-and-cost layer.
See the [Unravel Data comparison](https://lakesentry.io/compare/unravel-data-alternative).
### PointFive
A cloud and AI efficiency platform that detects and remediates waste across cloud infrastructure, data platforms, and AI services, with 60+ Databricks detections. It deploys agentless and read-only via a notebook, and remediates through AI-generated infrastructure-as-code fixes that engineers review and approve. Pricing is annual and scales with the spend it covers.
> **Fits:** teams that want one efficiency layer across the whole cloud estate, not Databricks alone.
See the [PointFive comparison](https://lakesentry.io/compare/pointfive-alternative).
### Espresso AI
An autonomous optimization engine for Snowflake and Databricks compute. It deploys with a SQL command and configuration, and optimizes in real time using machine learning. Pricing is results-based, billing a share of the savings delivered, with a money-back guarantee.
> **Fits:** teams that want compute cost cut hands-off and prefer to pay on results.
See the [Espresso AI comparison](https://lakesentry.io/compare/espresso-ai-alternative).
### LakeSight
A focused Databricks cost monitoring tool: cost breakdowns, run history, real-time tracking, rule-based alerts, and scheduled reports. It focuses on monitoring, at $49/month for 3 workspaces. It does not include statistical anomaly detection beyond rule-based alerts, or a ranked plan of what to change.
> **Fits:** teams that need clear cost visibility and reporting at a low price.
See the [LakeSight comparison](https://lakesentry.io/compare/lakesight-alternative).
### Zipher
Zipher began as a Databricks workload optimizer and has repositioned in 2026 as "The Intelligent Execution Layer for Agentic Workloads" — autonomous, zero-touch infrastructure management across data workloads, with Databricks as one target rather than the sole focus. Pricing is pay-as-you-go for the Growth tier and custom for Enterprise.
> **Fits:** teams wanting autonomous workload execution across platforms.
See the [Zipher comparison](https://lakesentry.io/compare/zipher-alternative).
## Where broad FinOps platforms fit
Multi-cloud FinOps platforms such as Finout manage cloud spend across AWS, Azure, GCP, Kubernetes, and SaaS, with Databricks as one integration among many. If your problem is allocating and governing total cloud spend and Databricks is a slice of it, a broad FinOps platform covers more of that surface than a Databricks-specific tool. If Databricks is where the spend and the questions concentrate, a Databricks-specific tool goes deeper.
## At a glance
| Tool | Scope | Pricing | Deployment | Optimization model |
|---|---|---|---|---|
| **Native tools** | Databricks (per account) | Included | Built-in | None (manual) |
| **LakeSentry** | Databricks cost intelligence | Public, flat per-user | Read-only service principal | Guided plans, applied by your team |
| **Unravel Data** | Multi-platform observability | Consumption-based, quoted | Cluster sensor + service principal | Autonomous remediation |
| **PointFive** | Cloud + data + AI efficiency | Annual, spend-tiered | Agentless notebook + service principal | IaC fixes, engineer-approved |
| **Espresso AI** | Snowflake + Databricks compute | Results-based | SQL command + config | Autonomous |
| **LakeSight** | Databricks cost monitoring | $49/mo, public | Workspace URL + token | None (monitoring) |
| **Zipher** | Agentic workload execution | Pay-as-you-go / custom | Workspace credentials (zero-touch) | Autonomous, zero-touch |
## How to choose
Start with the job, not the feature list.
If you only need to know what you spent, native tools or LakeSight answer that — native for free with some SQL, LakeSight for a low price with no setup work. If you need to know where spend goes and why, and which change to make next, a cost intelligence platform like LakeSentry adds attribution, statistical detection, and a ranked plan your team applies. If you want a bill cut automatically and are comfortable delegating decisions, an autonomous engine like Espresso AI fits. And if Databricks is one part of a wider estate, a broad platform like Unravel, PointFive, or Finout covers more ground at the cost of Databricks-specific depth.
The trade-off that runs through the category is breadth versus depth, and autonomy versus control. There is no single best tool — only the one that matches the job in front of you.
## Common questions
**What is the best Databricks cost tool?**
The one that matches your job. Native tools for single-workspace teams with engineering time; LakeSentry for Databricks-focused attribution, detection, and guided plans; autonomous engines for hands-off compute savings; broad platforms for multi-system estates.
**Which tools publish pricing?**
LakeSentry, LakeSight, PointFive, and Espresso AI publish pricing or a clear model. Unravel and Zipher route it through sales or pay-as-you-go without public per-tier figures.
**Do native tools make third-party tools unnecessary?**
Native tools cover free usage reporting. Third-party tools earn their place when you need cross-workspace consolidation, automatic attribution, anomaly detection, or optimization workflows that native tooling leaves you to build.
For a structured walk through reducing spend, see [Databricks cost optimization](https://lakesentry.io/blog/databricks-cost-optimization/), or start with the [FinOps for Databricks primer](https://lakesentry.io/blog/databricks-finops-101/).
---
## Databricks Native Cost Tools Alternative — LakeSentry
- URL: https://lakesentry.io/compare/databricks-native-cost-tools/
- Published: 2026-06-01
- Updated: 2026-08-05
- Category: comparison
- Tags: databricks, native-tools, alternative, comparison, cost-attribution
> An alternative to Databricks native cost tools for teams past system-table dashboards: cross-workspace attribution, anomaly detection, and guided optimization plans.
LakeSentry is a Databricks cost intelligence platform that reads the same system tables Databricks native cost tools use, then adds cross-workspace attribution, anomaly detection, and guided optimization plans on top. If your team has outgrown native dashboards and hand-written SQL, here is how LakeSentry compares on what each one does and where the work moves.
This page reflects the public state of Databricks native cost tooling as of May 2026, sourced from [Databricks documentation](https://docs.databricks.com/aws/en/admin/usage/).
## What native Databricks cost tools give you
Databricks ships real cost-management primitives, and they are free with the platform.
### System tables
[System tables](https://docs.databricks.com/aws/en/admin/system-tables/billing) such as `system.billing.usage` are the authoritative record of billable usage. Every cost tool, LakeSentry included, reads from them. For a single workspace with an engineer who is comfortable writing SQL, system tables plus a dashboard can answer most cost questions.
### AI/BI cost dashboards
Databricks provides importable cost-management dashboards built on system table data. An account admin can import one into a Unity Catalog-enabled workspace and customize it. These cover usage trends and breakdowns by workspace, SKU, and tag.
### Budgets and cluster policies
Budgets and budget alerts notify you when account or filtered spend crosses a threshold you set. [Cluster policies](https://docs.databricks.com/aws/en/admin/clusters/policies.html) prevent waste at creation time. Both are control-plane features no third-party tool replaces; they apply alongside any tool you add.
## Where teams hit the limits
Native tools answer "how much did we spend?" The questions that follow are where teams start writing their own SQL.
**Cross-workspace consolidation.** System tables are scoped to one metastore per region. A team with several workspaces stitches views together by hand, and that work grows with each new workspace.
**Attribution beyond the workspace.** Native breakdowns lean on consistent tagging. The day one team forgets to tag, the chargeback story has a gap. Attribution down to job, user, and team without manual tagging takes analysis system tables do not do on their own.
**Cost anomaly detection.** Databricks does not detect cost anomalies natively. Budget alerts fire on fixed thresholds, and Lakehouse Monitoring watches data quality, not DBU spend. Statistical spike detection is a project you build and tune on system tables.
**An optimization workflow.** System tables tell you a cluster ran. They do not tell you it was over-provisioned, or help you act on it safely. Translating raw usage into "this job is the one to look at" is analyst time, month after month.
## What LakeSentry adds
LakeSentry sits on top of native tools rather than replacing them. It connects through a read-only service principal, queries system tables, and normalizes the cost ledger across every workspace into one view. On top of that it adds automatic attribution by job, SQL warehouse, compute type, and team; anomaly detection with statistical evidence; and guided plans that name the change to make and the effect to expect. LakeSentry stays read-only — your team applies the change in Databricks.
> Native dashboards tell you spend changed. Where, why, and what to do next is where the manual SQL begins.
## At a glance
| | Native cost tools | DIY system tables + SQL | LakeSentry |
|---|---|---|---|
| **Source of truth** | System tables | System tables | Reads system tables |
| **Time to first insight** | Import a dashboard | Days of SQL | Connect read-only, minutes |
| **Cross-workspace view** | Per-workspace | If you build it | Built-in |
| **Attribution to job / user / team** | Tag-dependent | If you build it | Automatic |
| **Cost anomaly detection** | No (threshold alerts only) | If you build it | Statistical, built-in |
| **Path to the fix** | None | None | Guided plans, applied by your team |
| **Cost** | Included | Engineer time | $0 free / $499 / $849 per mo |
## Keep native, add LakeSentry
This is an addition, not a migration. System tables stay the source of truth, your finance team keeps any dashboards it relies on, and cluster policies keep doing their job. LakeSentry reads the same data through a read-only service principal, so it sits alongside native tools without touching the environment. It never requests write permissions.
## Choose native tools if
- You run one or a few workspaces and have engineering time to spend on cost SQL
- A platform engineer enjoys owning dashboards and ad-hoc analysis
- Your needs stop at usage reporting and threshold budget alerts
- You want zero added tooling in the stack
## Choose LakeSentry if
- You run several workspaces and want one consolidated cost ledger
- You want attribution to job and team without depending on complete tagging
- You want cost spikes surfaced statistically, not just at fixed budget thresholds
- You want each finding to arrive as a plan with its evidence, ranked by what it costs you
## Common questions
**Do I need to replace native tools?**
No. LakeSentry reads the same system tables and reports separately. Most teams keep native dashboards as a check and use LakeSentry as the daily cross-workspace view.
**Does Databricks detect cost anomalies on its own?**
Not for spend. Budget alerts use thresholds you set, and Lakehouse Monitoring covers data quality. Statistical cost-spike detection is something you build on system tables or get from a dedicated tool.
**What permissions does LakeSentry need?**
Read-only, through a Databricks service principal reading system tables. That is the only access it asks for — LakeSentry never requests write permissions and makes no changes in your environment.
For the top-to-bottom view of what native tooling shows and where it stops, see the deep dive on [native Databricks cost tools](https://lakesentry.io/blog/native-databricks-cost-tools/). For how LakeSentry compares to the other tools in this category, see the [Databricks cost tools comparison](https://lakesentry.io/compare/databricks-cost-tools).
---
## Espresso AI Alternative: LakeSentry for Databricks
- URL: https://lakesentry.io/compare/espresso-ai-alternative/
- Published: 2026-06-01
- Updated: 2026-08-05
- Category: comparison
- Tags: espresso-ai, alternative, comparison, databricks, cost-attribution
> A Databricks-only alternative to Espresso AI. Compare scope, how each one acts on cost, and pricing — based on each product's public materials.
LakeSentry is a Databricks cost intelligence platform with public per-user pricing and guided optimization plans — it stays read-only, and your team applies every change in Databricks. If you are evaluating [Espresso AI](https://www.espresso.ai/), here is how LakeSentry compares on scope, how each one acts on cost, and pricing.
This page is based on each company's current public materials as of May 2026.
## What each product is
### Espresso AI
Espresso AI is an autonomous optimization engine for data warehouses. It positions itself as a "superhuman DBA" that monitors and optimizes Snowflake and Databricks compute in real time using machine learning, and it deploys by running a SQL command and applying some configuration. It runs hands-off: once connected, it acts to reduce compute cost without ongoing operator involvement.
### LakeSentry
LakeSentry is purpose-built for Databricks. It connects read-only through a service principal, queries system tables, and normalizes the cost ledger across workspaces: spend by job, SQL warehouse, compute type, and team, plus anomaly detection with statistical evidence. Every recommendation ships as a guided plan your team applies in Databricks; LakeSentry itself stays read-only.
## Different jobs
The two products solve adjacent problems.
Espresso is an optimization engine. Its primary job is to reduce compute cost automatically, and the output is a lower bill rather than a dashboard you read.
LakeSentry is a cost intelligence platform. Its primary job is to show where the money goes by team and job, surface anomalies, and rank what to change next. Visibility and attribution are direct outputs, not a side effect of optimization.
A team that wants the bill reduced with minimal involvement is buying something different from a team that wants to attribute spend before changing anything. They are different purchases.
## Different ways of acting on cost
Espresso is autonomous by design. A SQL command and configuration to deploy, then continuous ML-driven optimization; the model carries the optimization work without ongoing operator input.
LakeSentry does not act on your environment. It reads, explains, and hands the change to you:
- **Read-only connection** — a service principal that queries system tables; LakeSentry never requests write permissions
- **Evidence with every finding** — baseline, z-score, and dollar impact, so you can judge the signal before you act on it
- **Guided plans** — what to change, its current value, and the effect to expect, ranked by impact; your team applies the change in Databricks, and approvals and dismissals land in an audit log
The difference is where the work sits. Autonomous optimization hands compute decisions to the tool. LakeSentry hands your team the evidence and the plan, and nothing changes until someone on your side makes the change.
## Pricing
LakeSentry's pricing is published on [lakesentry.io](https://lakesentry.io/pricing/):
- **Free:** $0/mo — 1 user, 3 months history, unlimited connected workspaces
- **Standard:** $499/mo (billed annually) — up to 5 users, 12 months history
- **Pro:** $849/mo (billed annually) — unlimited users, unlimited history
There are no per-DBU and no per-workspace fees; cost tracks user count, not savings.
Espresso AI uses results-based pricing, published on [its pricing page](https://www.espresso.ai/). The plans bill a share of the savings delivered: its Single-Shot plan bills 40% of monthly savings, and it lists other tiers, with a money-back guarantee and no minimums or long-term commitment. The model is structured so that if savings do not materialize, you do not pay.
The two pricing models differ structurally. Results-based pricing ties cost to the compute savings delivered, and depends on an agreed measurement and baseline. Flat per-user pricing is fixed regardless of savings and covers visibility and attribution whether or not an optimization fires.
## At a glance
| | Espresso AI | LakeSentry |
|---|---|---|
| **Category** | Autonomous warehouse compute optimization | Databricks cost intelligence |
| **Platform scope** | Snowflake + Databricks | Databricks-only |
| **Primary job** | Reduce compute cost automatically | Visibility, attribution, anomalies, guided plans |
| **Path to the fix** | Autonomous; SQL command + config to deploy | Guided plans with evidence, applied by your team |
| **Pricing** | Results-based (share of savings) | Flat per-user: $0 / $499 / $849/mo (billed annually) |
| **Free tier / trial** | Money-back guarantee | Free: 1 user, 3 months history, unlimited workspaces |
## Choose Espresso AI if
- Reducing compute cost automatically is the outcome you want
- You run Snowflake as well as Databricks and want one optimization engine across both
- Results-based pricing fits how you want to pay, and you have an agreed savings baseline
- A hands-off, autonomous model matches your team's preference
## Choose LakeSentry if
- You want to see where Databricks spend goes by team and job before changing anything
- Anomaly detection and attribution are part of what you need, alongside optimization
- You want to review the evidence and make each change yourself, rather than hand compute decisions to a tool
- Flat, predictable pricing fits your procurement rather than a share of savings
## Common questions
**Are these competing or complementary?**
Mostly complementary. Espresso cuts compute cost; LakeSentry adds the attribution and anomaly detection an optimization engine does not provide. Because it stays read-only, it can run alongside one.
**Does LakeSentry guarantee savings?**
No. LakeSentry does not make blanket savings claims or price on them. It provides visibility and guided plans; what you save depends on your environment and which plans you apply.
**Which is more predictable to budget?**
Flat per-user pricing is fixed regardless of outcome. Results-based pricing varies with the savings achieved.
For the full category view, see the [Databricks cost tools comparison](https://lakesentry.io/compare/databricks-cost-tools), or read the primer on [DBUs and where Databricks cost comes from](https://lakesentry.io/blog/databricks-dbu-explained/).
---
## LakeSight Alternative: LakeSentry for Databricks Cost
- URL: https://lakesentry.io/compare/lakesight-alternative/
- Published: 2026-06-01
- Updated: 2026-08-05
- Category: comparison
- Tags: lakesight, alternative, comparison, databricks, cost-attribution
> A LakeSight alternative for teams that need more than monitoring. Compare scope, anomaly detection, and pricing — based on each product's public materials.
LakeSentry is a Databricks cost intelligence platform that covers cost monitoring and extends into statistical anomaly detection and guided optimization plans. If you are evaluating [LakeSight](https://www.lakesight.io/), here is how the two compare on scope, detection, and pricing.
This page is based on each company's current public materials as of May 2026.
## What each product is
### LakeSight
LakeSight is a Databricks cost monitoring tool. Its stated promise is "Databricks cost monitoring, without the complexity." You connect a workspace with a URL and token, with no cloud-provider access required, and track costs by job, cluster, run, and tag. It provides cost breakdowns by node type, billing type, and Photon usage; run history with per-run VM and DBU detail; real-time tracking of running jobs and interactive clusters; alert rules for job failures and abnormal durations; scheduled cost reports by email; and a single dashboard across multiple workspaces. Its scope is monitoring and reporting.
### LakeSentry
LakeSentry is also Databricks-only and also connects read-only. It covers the same monitoring ground (spend by job, SQL warehouse, compute type, and team), then extends it with anomaly detection backed by statistical evidence and guided plans for what to change. LakeSentry stays read-only; your team applies the change in Databricks.
## Where the scope differs
LakeSight is a monitoring and reporting product. Its output is an answer to "what did we spend, and on what?", delivered as breakdowns, run-level detail, and recurring reports. For teams whose need is cost visibility, that is the scope of the job.
LakeSentry covers that same monitoring layer and adds two areas LakeSight does not cover:
- **Statistical anomaly detection.** LakeSight's alerts are rule-based — notify on job failure or abnormal duration. LakeSentry adds detection of cost anomalies with statistical evidence, which surfaces a spend pattern that drifts without a fixed rule.
- **A ranked plan to act on.** LakeSight reports what is happening. LakeSentry adds the step after that: each finding becomes a guided plan — the evidence, the exact change proposed, and its dollar impact — that your team applies in Databricks. LakeSentry stays read-only throughout.
The difference is scope. LakeSight covers monitoring; LakeSentry adds anomaly detection and optimization on top, at a higher price.
## Pricing
LakeSight publishes pricing on [its pricing page](https://www.lakesight.io/pricing): $49/month for 3 workspaces and up to 20 team members, plus $29/month for each additional workspace, with a 14-day free trial and no card required.
LakeSentry's pricing is published on [lakesentry.io](https://lakesentry.io/pricing/):
- **Free:** $0/mo — 1 user, 3 months history, unlimited connected workspaces
- **Standard:** $499/mo (billed annually) — up to 5 users, 12 months history
- **Pro:** $849/mo (billed annually) — unlimited users, unlimited history
The two price on different axes. LakeSight prices by workspace count — its $49/month covers 3 workspaces and up to 20 team members, and each additional workspace is +$29/month. LakeSentry prices by users: Free is 1 user, Standard ($499/mo) up to 5 users, Pro ($849/mo) unlimited users, with unlimited workspaces on every tier. So which is cheaper depends on your shape: many workspaces with few users favors LakeSight; many users across many workspaces favors LakeSentry. The plans also differ in scope: LakeSight is monitoring, while LakeSentry's tiers add anomaly detection and optimization, so they aren't like-for-like on price.
## At a glance
| | LakeSight | LakeSentry |
|---|---|---|
| **Category** | Databricks cost monitoring | Databricks cost intelligence |
| **Cost breakdown + run history** | Yes | Yes |
| **Alerts** | Rule-based (failures, durations) | Statistical anomaly detection |
| **Path to the fix** | None (monitoring only) | Guided plans with evidence, applied by your team |
| **Workspaces** | 3 included, +$29/mo each | Unlimited on every tier |
| **Pricing** | $49/mo paid plan | $0 / $499 / $849/mo (per-user) |
| **Free option** | 14-day trial | Free tier ($0) |
## Choose LakeSight if
- Your need is cost visibility and run-level detail
- Emailed scheduled reports and rule-based alerts cover your monitoring needs
- A lower price for a monitoring-only tool fits your budget
- You want the smallest footprint for Databricks cost tracking
## Choose LakeSentry if
- You want monitoring plus statistical anomaly detection on spend
- You want a path from seeing a problem to a ranked plan for fixing it
- Unlimited workspaces on a flat per-user plan fits your structure
- Attribution by team and job for chargeback is part of what you need
## Common questions
**Do LakeSight and LakeSentry overlap?**
Yes, on monitoring. Both provide cost breakdowns, run history, and multi-workspace views. LakeSentry adds statistical anomaly detection and guided optimization plans on top of that layer.
**Does LakeSentry cost more than LakeSight?**
Yes. LakeSight's paid plan is $49/month; LakeSentry's paid tiers are $499 and $849/month. The difference corresponds to scope — LakeSentry adds anomaly detection and optimization beyond monitoring.
**Can LakeSentry replace LakeSight?**
LakeSentry covers the monitoring LakeSight provides and adds detection and optimization, so it can serve as a replacement. Whether the added scope is needed depends on whether you require detection and optimization or only monitoring.
For the full category view, see the [Databricks cost tools comparison](https://lakesentry.io/compare/databricks-cost-tools), or read about [diagnosing Databricks spend changes](https://lakesentry.io/blog/databricks-spend-changes/) when monitoring alone is not enough.
---
## PointFive Alternative: LakeSentry for Databricks Cost
- URL: https://lakesentry.io/compare/pointfive-alternative/
- Published: 2026-06-01
- Updated: 2026-08-05
- Category: comparison
- Tags: pointfive, alternative, comparison, databricks, cost-attribution
> A Databricks-only alternative to PointFive. Compare scope, remediation model, and pricing — based on each product's public materials.
LakeSentry is a Databricks cost intelligence platform with public per-user pricing and guided optimization plans — it stays read-only, and your team applies every change in Databricks. If you are evaluating [PointFive](https://www.pointfive.co/databricks), here is how LakeSentry compares on scope, remediation model, and pricing.
This page is based on each company's current public materials as of May 2026.
## What each product is
### PointFive
PointFive positions itself as a cloud and AI efficiency platform — "extend your coverage to every resource and layer to create a single source of truth for Cloud, Data, PaaS & AI Services cost efficiency." Its DeepWaste detection spans cloud infrastructure, data platforms, and AI services. On Databricks it lists 60+ detections: DBU, compute, storage, and serverless visibility; per-job serverless attribution; cluster right-sizing; multi-node waste; storage and Time Travel optimization; and ML serving rightsizing. It deploys agentless and read-only through a single notebook run. Remediation is agentic but human-reviewed: it generates infrastructure-as-code fixes (Terraform, CloudFormation) that engineers review and approve, with routing into Jira, Slack, or ServiceNow.
### LakeSentry
LakeSentry is purpose-built for Databricks. It connects read-only through a service principal, queries system tables, and normalizes the cost ledger across workspaces: spend by job, SQL warehouse, compute type, and team, plus anomaly detection with statistical evidence. Every recommendation ships as a guided plan your team applies in Databricks; LakeSentry itself stays read-only.
## Different scope
PointFive's coverage spans cloud infrastructure, several data platforms, PaaS, and AI services, with Databricks as one layer within that wider picture. LakeSentry covers Databricks only.
LakeSentry's cost ledger, its use of system tables as the source of truth, and Unity Catalog as the access boundary are all built around the Databricks model. PointFive's surface extends from cloud infrastructure through data platforms to AI inference.
If Databricks is the layer you are optimizing, LakeSentry's scope is specific to it. If you want to find waste across the whole cloud estate from EC2 to AI inference in one tool, PointFive covers that wider surface.
## Similar deployment, different remediation
Both products connect read-only. Each deploys agentless and authenticates through a service principal with minimal permissions. PointFive keeps write access optional; LakeSentry never asks for it.
The remediation paths differ:
- **PointFive** generates fixes as infrastructure-as-code (Terraform, CloudFormation) that your engineers review and approve before deploying, with routing into Jira, Slack, or ServiceNow.
- **LakeSentry** delivers each finding as a guided plan in-product: the evidence, the exact change proposed, and the current value it would replace, ranked by dollar impact. Your team applies it in Databricks; approvals and dismissals are admin-only and land in an audit log.
Both keep a human in the loop. The difference is what arrives in your hands — generated infrastructure-as-code to review and deploy, or a reviewed plan with the evidence attached that your own team applies.
## Pricing
LakeSentry's pricing is published on [lakesentry.io](https://lakesentry.io/pricing/):
- **Free:** $0/mo — 1 user, 3 months history, unlimited connected workspaces
- **Standard:** $499/mo (billed annually) — up to 5 users, 12 months history
- **Pro:** $849/mo (billed annually) — unlimited users, unlimited history
There are no per-DBU and no per-workspace fees.
PointFive's pricing is annual and scales with the cloud spend it covers; its Databricks page cites a ratio of "less than $35/month per $1M of Databricks spend," with larger tiers quoted by contract. The structural difference: PointFive's cost tracks the spend it covers, while LakeSentry's tracks your user count and stays flat as your Databricks bill grows or shrinks.
Which is lower depends on your numbers. Spend-tiered pricing rises with the bill it covers; flat per-user pricing stays the same as spend changes.
## At a glance
| | PointFive | LakeSentry |
|---|---|---|
| **Category** | Cloud + data + AI efficiency platform | Databricks cost intelligence |
| **Scope** | Cloud infra, multiple data platforms, AI services | Databricks-only |
| **Deployment** | Agentless, read-only, notebook + service principal | Read-only, service principal |
| **Remediation model** | AI-generated IaC fixes, engineer-approved | Guided plans with evidence, applied by your team |
| **Pricing** | Annual, scales with spend covered | Flat per-user: $0 / $499 / $849/mo (billed annually) |
| **Free tier / trial** | No free tier; demo (also on AWS Marketplace) | Free: 1 user, 3 months history, unlimited workspaces |
## Choose PointFive if
- You want one efficiency layer across cloud infrastructure, data platforms, and AI services
- Reviewing and deploying AI-generated infrastructure-as-code fixes fits how your engineers work
- Annual pricing that scales with the spend it covers suits your budgeting
- DeepWaste detection beyond Databricks is part of what you are buying
## Choose LakeSentry if
- Databricks is your focus and you want cost attribution and anomaly depth there
- You want the evidence and the proposed change in one place rather than IaC-and-ticketing remediation
- Flat per-user pricing that stays the same as spend changes fits your procurement
- You want a single cost ledger across all your Databricks workspaces
## Common questions
**Do the two overlap on Databricks?**
Yes, on detection. Both surface Databricks waste. PointFive does this as part of a cloud efficiency platform; LakeSentry does it with Databricks-specific attribution.
**How does remediation differ?**
Both connect agentless and read-only. PointFive delivers fixes as infrastructure-as-code that engineers review and approve; LakeSentry delivers guided plans in-product — the evidence, the exact change, and its expected effect — which your team applies in Databricks.
**What if my waste is not only in Databricks?**
PointFive's coverage spans the whole cloud estate. LakeSentry's coverage is Databricks, where it goes into per-job and per-team attribution.
For the full category view, see the [Databricks cost tools comparison](https://lakesentry.io/compare/databricks-cost-tools), or read how LakeSentry approaches [Databricks cost optimization](https://lakesentry.io/blog/databricks-cost-optimization/).
---
## Unravel Data Alternative: LakeSentry for Databricks
- URL: https://lakesentry.io/compare/unravel-data-alternative/
- Published: 2026-06-01
- Updated: 2026-08-05
- Category: comparison
- Tags: unravel-data, alternative, comparison, databricks, cost-attribution
> A Databricks-only alternative to Unravel Data. Compare scope, how each one acts on cost, and pricing — based on each product's public materials.
LakeSentry is a Databricks cost intelligence platform with public per-user pricing and guided optimization plans — it stays read-only, and your team applies every change in Databricks. If you are evaluating [Unravel Data](https://www.unraveldata.com/), here is how LakeSentry compares on scope, how each one acts on cost, and pricing.
This page is based on each company's current public materials as of May 2026.
## What each product is
### Unravel Data
Unravel is an AI-native data observability platform. Its public positioning: "Your data platform costs too much and runs too slow. Unravel fixes both. Automatically." It frames itself as an operator, not only an advisor, and spans Databricks, Snowflake, BigQuery, EMR, and Cloudera. On Databricks it covers cost analytics plus performance work such as code rewriting, cluster configuration, shuffle fixes, and autoscaling correction.
### LakeSentry
LakeSentry is purpose-built for Databricks. It connects read-only through a service principal, queries system tables, and normalizes the cost ledger across workspaces: spend by job, SQL warehouse, compute type, and team, plus anomaly detection and idle-resource findings. Every recommendation ships as a guided plan your team applies in Databricks; LakeSentry itself stays read-only.
## Different scope
Scope is the main difference between the two.
Unravel is a multi-platform performance-and-cost product: one observability layer across several data engines, with application-level performance tuning alongside cost. If your stack spans Databricks plus Snowflake or BigQuery, that breadth consolidates tools into one.
LakeSentry is Databricks-only, and the depth is the trade-off. The cost ledger, system tables as the source of truth, and Unity Catalog as the access boundary are all shaped around the Databricks model rather than generalized across engines.
If your spend is concentrated in Databricks, LakeSentry's narrower scope is specific to it. If you operate several data platforms and want one tool across all of them, Unravel's scope covers them.
## Different ways of acting on cost
Unravel leads with autonomous remediation — "fixes both, automatically" is the headline claim, with its Arvix AI positioned to act rather than just recommend. That suits teams that want the tool to carry optimization work with minimal hands-on involvement.
LakeSentry does not act on your environment. It reads, explains, and hands the change to you:
- **Read-only connection** — a service principal that queries system tables; LakeSentry never requests write permissions
- **Evidence with every finding** — baseline, z-score, and dollar impact, so you can judge the signal before you act on it
- **Guided plans** — what to change, its current value, and the effect to expect, ranked by impact; your team applies the change in Databricks, and approvals and dismissals land in an audit log
Neither model is universally better. Autonomous remediation suits teams that prefer to hand off operational decisions. A guided plan suits teams that want the reasoning in front of them and the change made by someone who owns the workload.
## Pricing
LakeSentry's pricing is published on [lakesentry.io](https://lakesentry.io/pricing/):
- **Free:** $0/mo — 1 user, 3 months history, unlimited connected workspaces
- **Standard:** $499/mo (billed annually) — up to 5 users, 12 months history
- **Pro:** $849/mo (billed annually) — unlimited users, unlimited history
There are no per-DBU and no per-workspace fees; the per-user tiers are the full picture.
Unravel does not publish per-tier pricing. Public descriptions of its model point to consumption-based billing tied to the DBU, warehouse, or slot usage it monitors, available annually or pay-as-you-go, and quoted through a demo. Reviews and pricing data appear on [G2](https://www.g2.com/products/unravel-data/reviews) and Capterra if you want third-party reference points.
The practical difference is procurement timing. A flat per-user number on the page shortens the path when procurement wants a figure before approving an evaluation; consumption-based pricing scales with what you monitor and usually involves a quote.
## At a glance
| | Unravel Data | LakeSentry |
|---|---|---|
| **Category** | Multi-platform data observability (cost + performance) | Databricks cost intelligence |
| **Platform scope** | Databricks, Snowflake, BigQuery, EMR, Cloudera | Databricks-only |
| **Primary job** | Performance and cost together | Cost visibility, attribution, anomalies |
| **Path to the fix** | Autonomous remediation | Guided plans with evidence, applied by your team |
| **Access it asks for** | Active optimization | Read-only, always |
| **Pricing** | Consumption-based, quoted (no public tiers) | Public per-tier: $0 / $499 / $849/mo (billed annually) |
| **Free tier / trial** | Free assessment / demo | Free: 1 user, 3 months history, unlimited workspaces |
## Choose Unravel if
- You run more than one data platform and want a single observability layer across them
- Performance tuning matters as much as cost in your decision
- You want autonomous remediation that acts with minimal operator involvement
- Application-level root-cause analysis is part of what you are buying
## Choose LakeSentry if
- Databricks is the bulk of your data spend and you want cost depth there
- You want to see everything first, from a tool that never asks for write access
- Public, predictable per-user pricing helps your procurement process
- You want every change proposed with its evidence, approved in the open, and made by your own team
## Common questions
**Can I evaluate both at once?**
Yes. LakeSentry runs read-only, so it sits beside any other tool without touching the environment, and the free tier needs no card.
**Does LakeSentry do performance tuning?**
No. LakeSentry is cost-focused: attribution, anomaly detection, and guided plans for the cost changes worth making. Cross-platform performance APM is part of Unravel's wider scope, not LakeSentry's.
**What if Databricks is only part of my stack?**
If Databricks is the bulk of your spend, LakeSentry's depth fits and other platforms can keep their own tooling. If your platforms are roughly equal in size, a broader tool such as Unravel may fit the whole estate.
For the full category view, see the [Databricks cost tools comparison](https://lakesentry.io/compare/databricks-cost-tools), or read how LakeSentry approaches [Databricks cost optimization](https://lakesentry.io/blog/databricks-cost-optimization/) end to end.
---